Model Comparison
DeepSeek V4.1 Flash vs V4 Pro: Which Should You Use?
DeepSeek V4.1 Flash vs V4 Pro: compare API prices, image input and retirement dates. Check whether your old model name still selects the old version.
ReadDeepSeek V4.1 Flash vs V4 Pro: compare API prices, image input and retirement dates. Check whether your old model name still selects the old version.
Read
Images 2.5 vs Nano Banana 2: SandBase API samples compare Flare, Sunburst and Nano Banana 2 on surreal scenes, visual humor and a shared-reference edit.
Read
GPT Image 2.5 Flare vs Sunburst: compare speed, editing precision, quality settings and official pricing, with a headphone recoloring example showing what a local edit preserves.
Read
SandBase's GPT-6 Astra vs Claude Fable 5.1 test: the same 3D game prompt, original code, startup failures, completion checks, response times and actual API charges.
Read
Compare GPT-6 Astra, Claude Fable 5.1, and Gemini 3.8 Flash for agents: task fit, retry budgets, escalation rules, and limits of cross-benchmark rankings.
Read
WorkBuddy, CodeBuddy, and Claude Code overlap, but they optimize for different work surfaces. Compare scope, tools, control, and hand-off before choosing.
Read
Calculate Gemini 3.8 Flash coding costs including thinking tokens, compare provider rates, and cap retries at two before escalating a failed patch.
Read
SandBase compares Fable 5.1 and Mythos 5.1 access, API pricing, fallback and retention. Learn why a Fable API account does not grant Mythos research permissions.
Read
Three AI labs now ship cybersecurity-focused models. Comparing GLM-5.3, Anthropic Mythos 5, and OpenAI Daybreak on vulnerability discovery, exploits, and defense.
Read
Compare OpenAI API alternatives for direct model access, OpenAI-compatible migration, self-hosting, routing, image and video APIs.
Read
Compare OpenRouter alternatives for one LLM API, self-hosting, routing, observability, and multimodal tools: SandBase, LiteLLM, Portkey, and Cloudflare.
Read
Compare Google Cloud API Gateway model routing, LiteLLM, and OpenRouter on model reach, routing control, fallbacks, data boundaries, cost, and operations.
Read
DeepSeek Harness vs Claude Managed Agents compared. Open-source composable plugins vs managed hosted infrastructure. Architecture, trade-offs, and when to pick each.
Read
DeepSeek Harness vs Hermes Agent, with OpenClaw compared: architecture, setup, extensibility, channels, learning loops, and which open-source AI agent fits each use case in 2026.
Read
Three-way comparison of SandBase Managed Agents, Claude Managed Agents, and DeepSeek Harness covering architecture, pricing, and data ownership.
Read
Cursor vs Windsurf vs Claude Code compared in 2026. IDE integration, agent autonomy, model flexibility, multi-file editing, MCP support, and pricing — with a verdict per use case.
Read
Muse Spark 1.2 vs Claude Sonnet 5: compare coding-agent benchmarks, API pricing, subagents, speed, reliability, and which model fits your workflow.
Read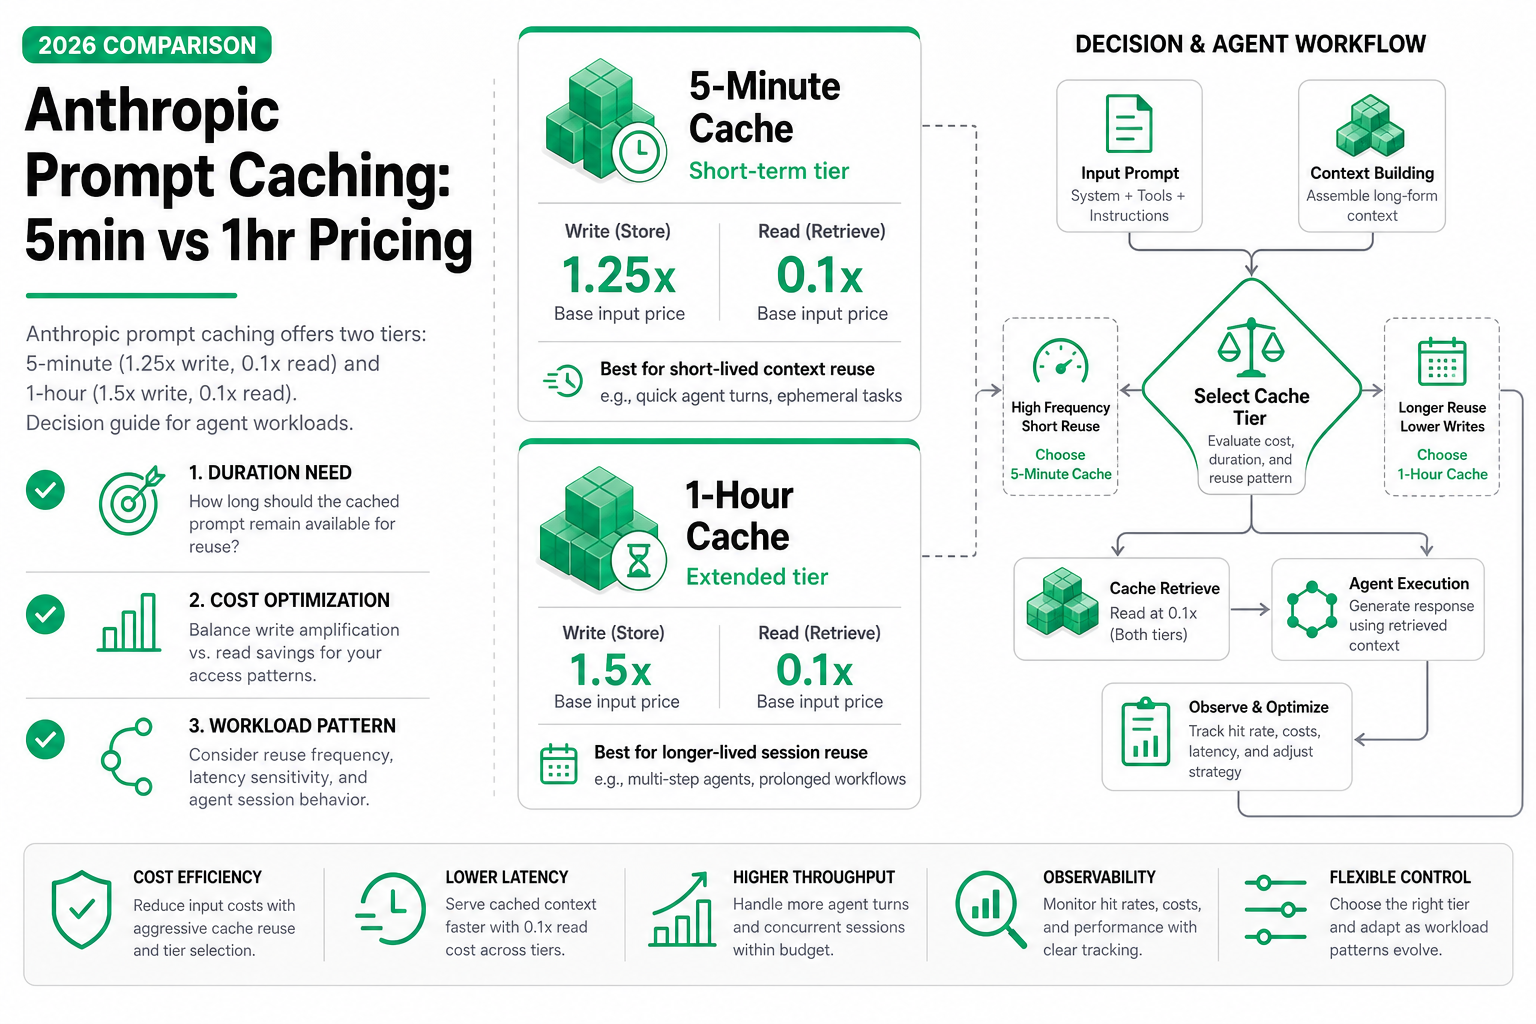
Anthropic prompt caching offers two tiers: 5-minute (1.25x write, 0.1x read) and 1-hour (1.5x write, 0.1x read). Decision guide for agent workloads.
Read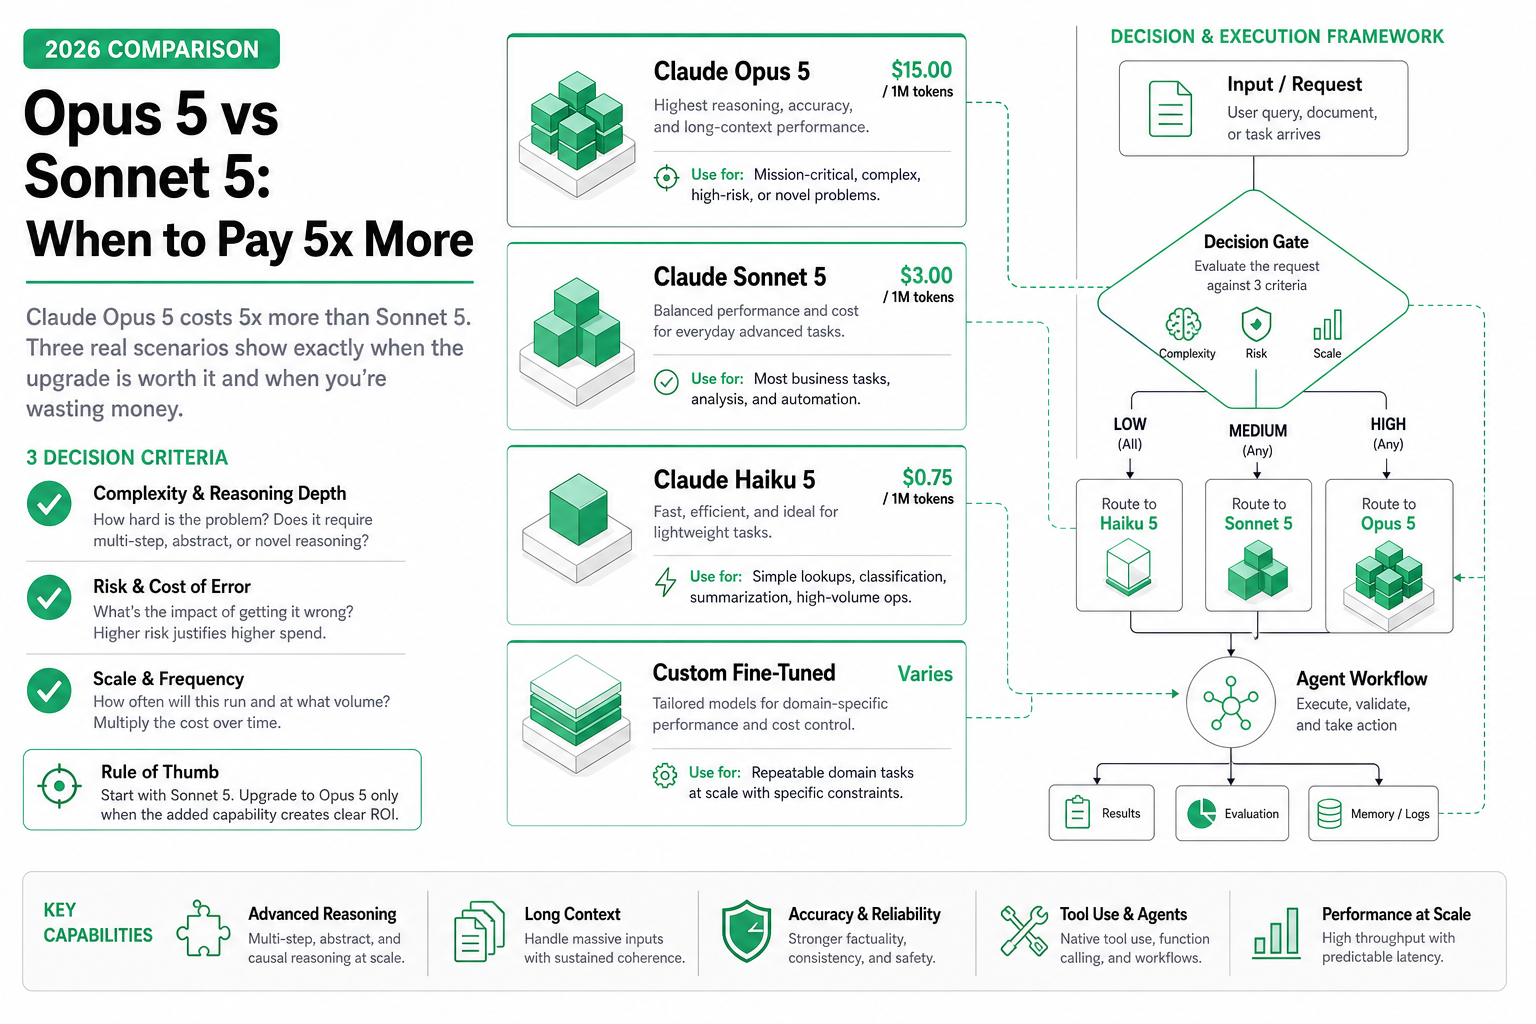
Claude Opus 5 is listed at $5/$25 per MTok and Sonnet 5 at $2/$10. Compare their shared 1M context, speed positioning, and a practical evaluation route.
Read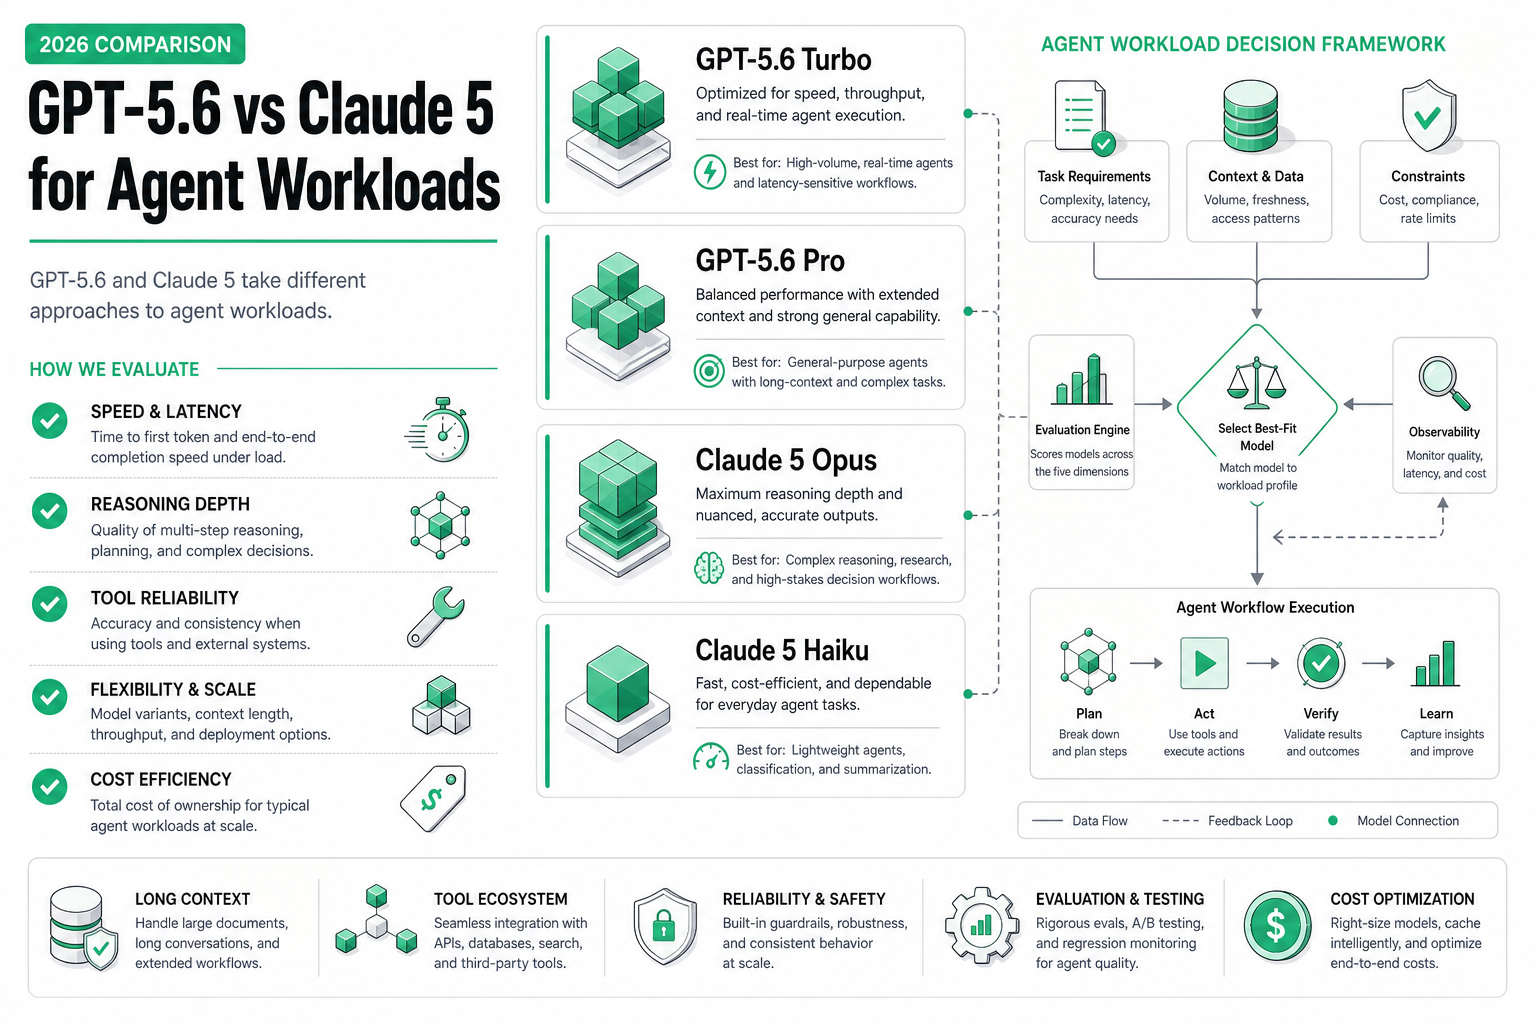
GPT-5.6 and Claude 5 take different approaches to agent workloads. Speed and variants vs reasoning depth and tool reliability. Scenario-based comparison.
Read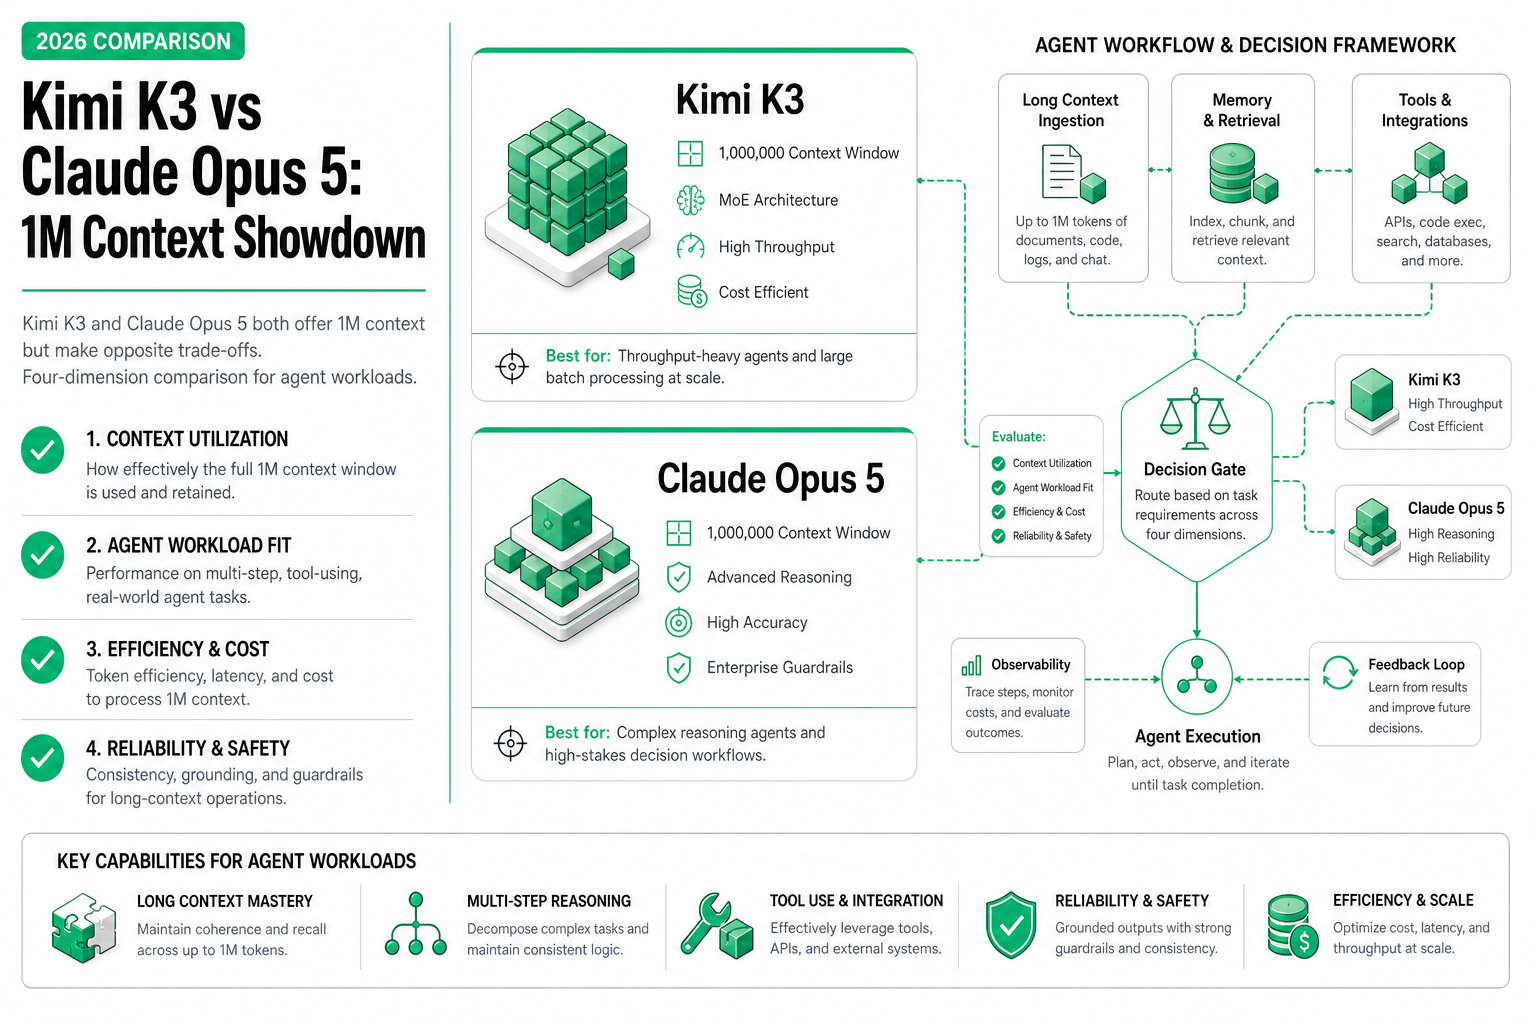
Kimi K3 and Claude Opus 5 both offer 1M context but make opposite trade-offs. Four-dimension comparison for agent workloads.
Read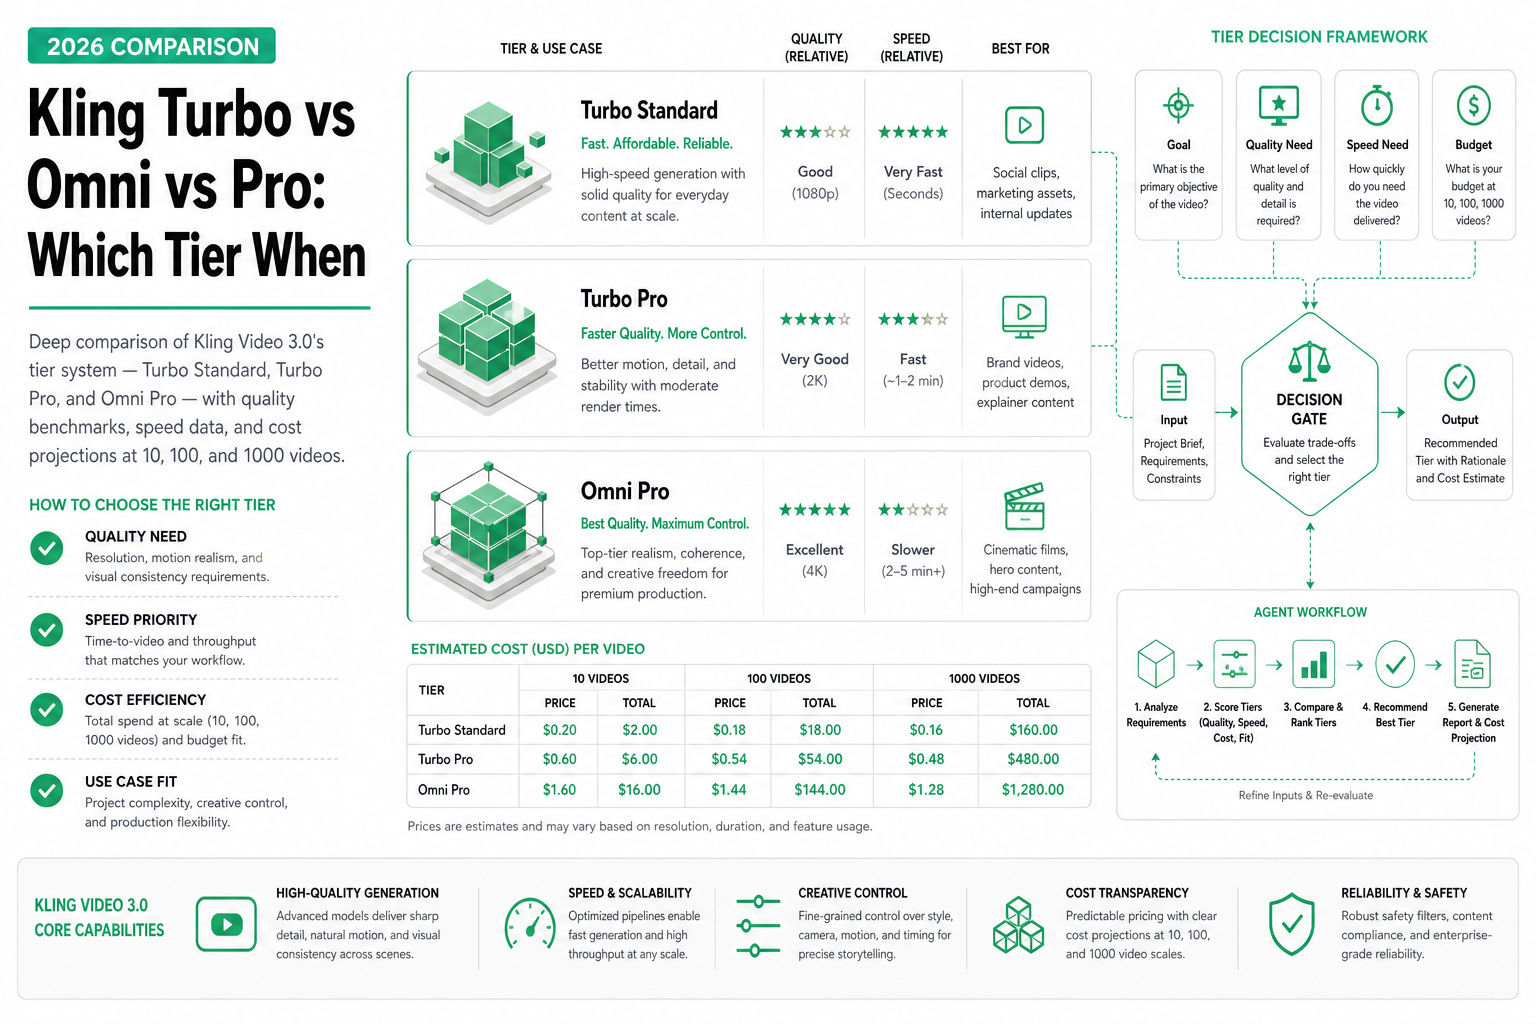
Deep comparison of Kling Video 3.0's tier system — Turbo Standard, Turbo Pro, and Omni Pro — with quality benchmarks, speed data, and cost projections at 10, 100, and 1000 videos.
Read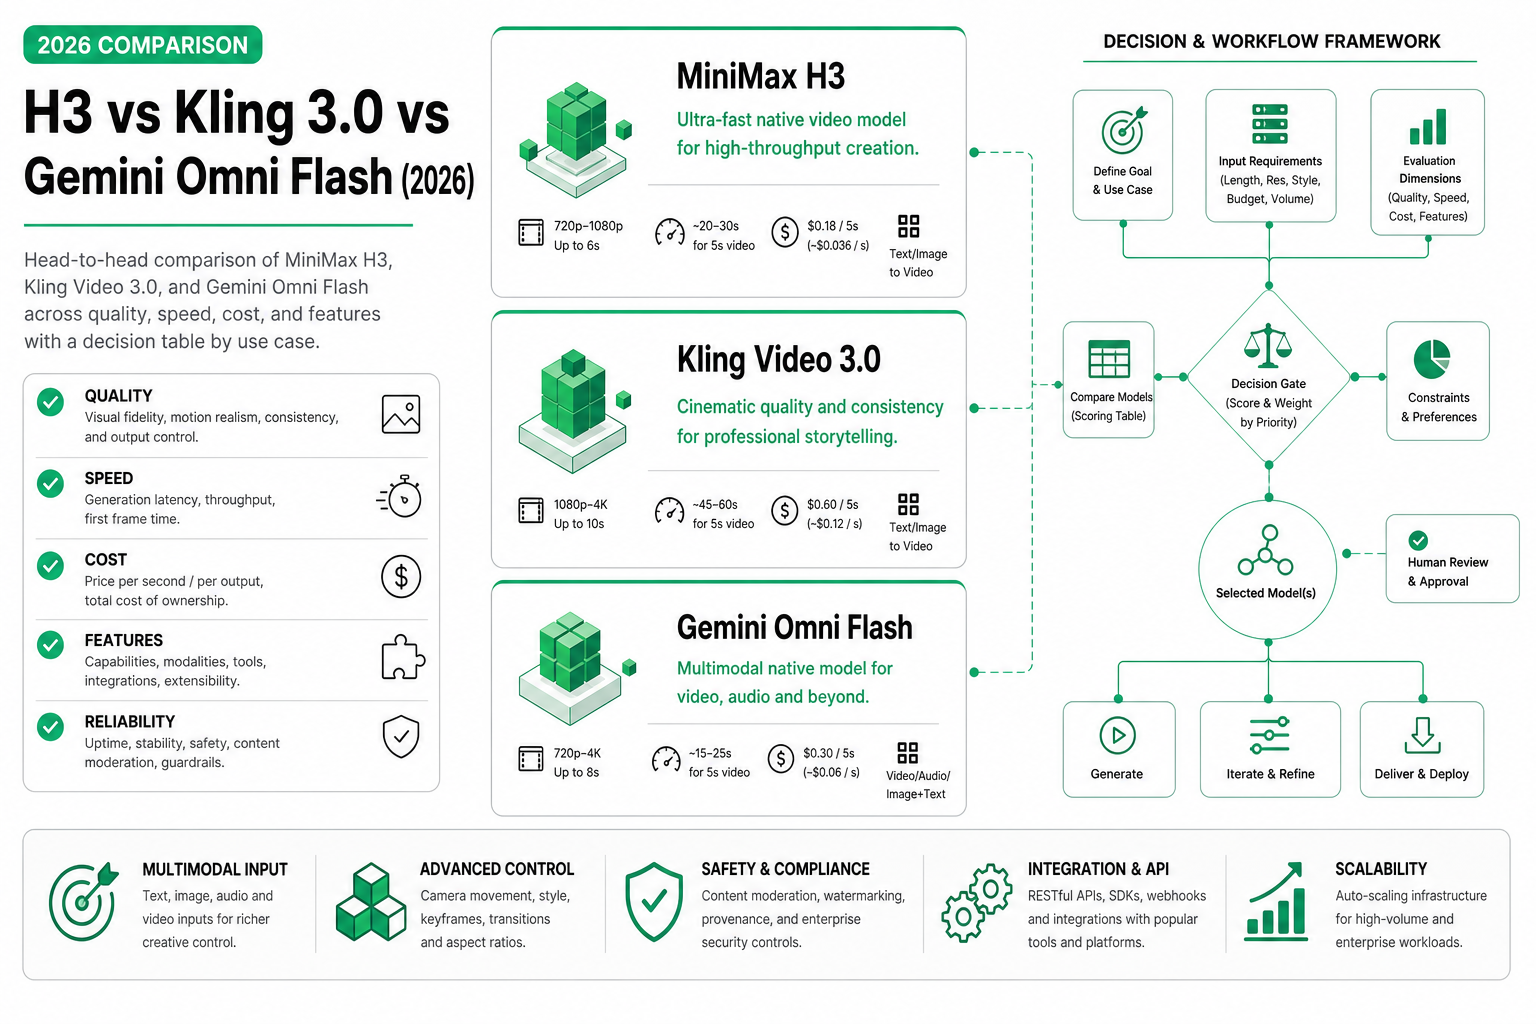
MiniMax H3 vs Kling Video 3.0 vs Gemini Omni Flash: which video API is best? Compare pricing, quality, audio, speed, and AI agent use cases in 2026.
Read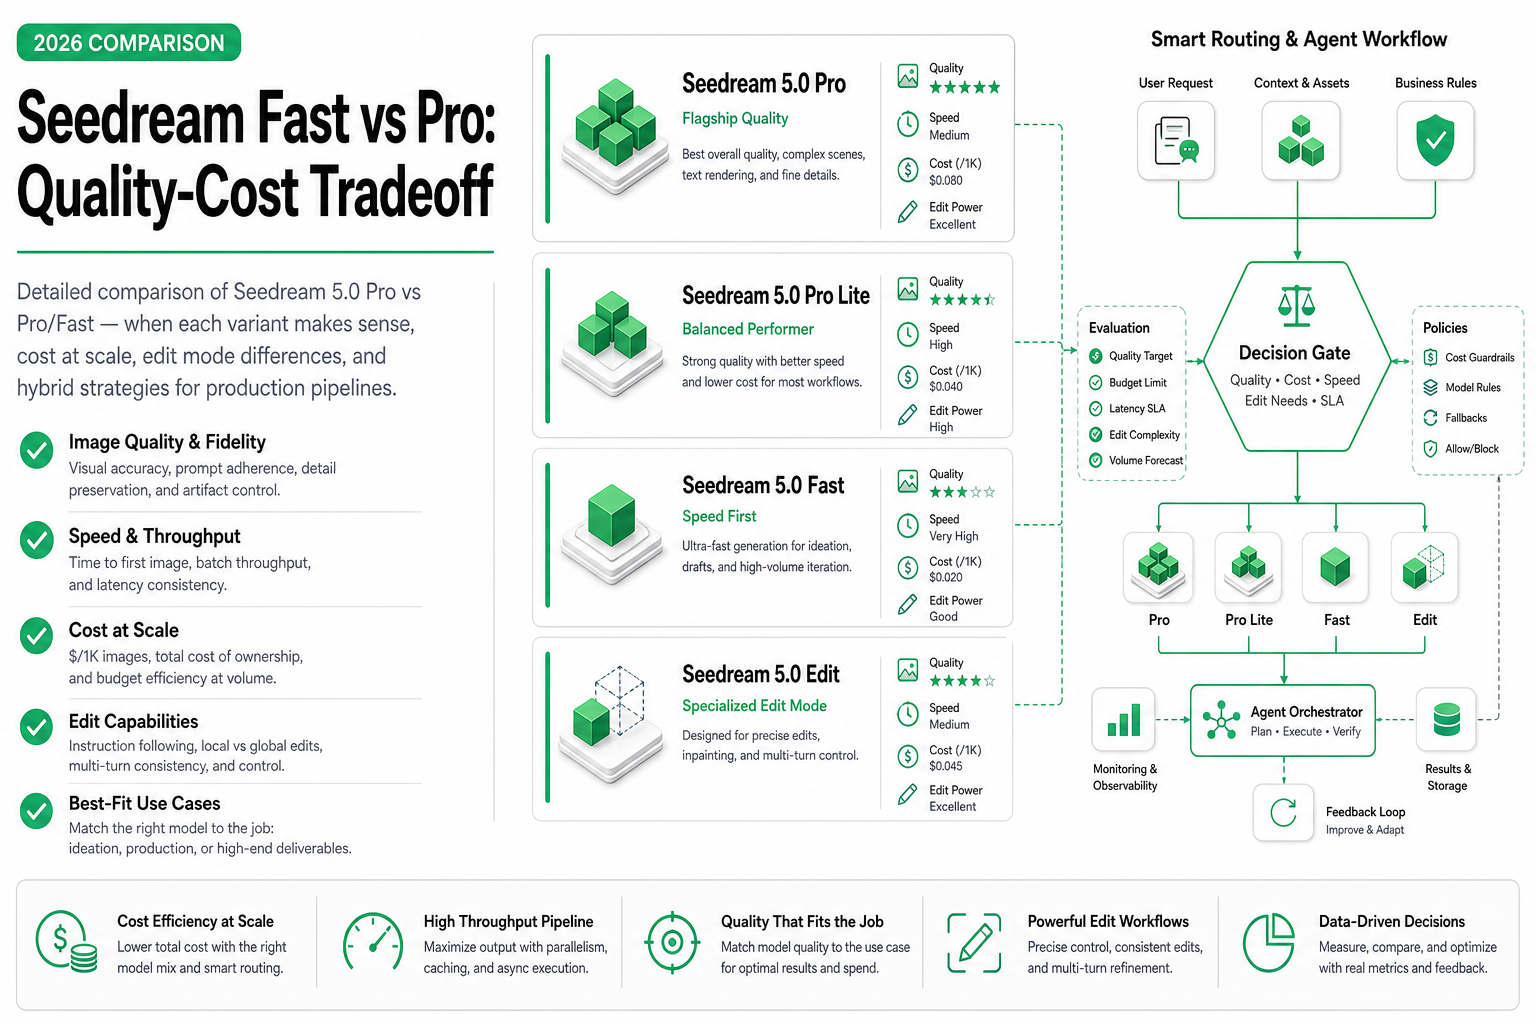
Detailed comparison of Seedream 5.0 Pro vs Pro/Fast — when each variant makes sense, cost at scale, edit mode differences, and hybrid strategies for production pipelines.
Read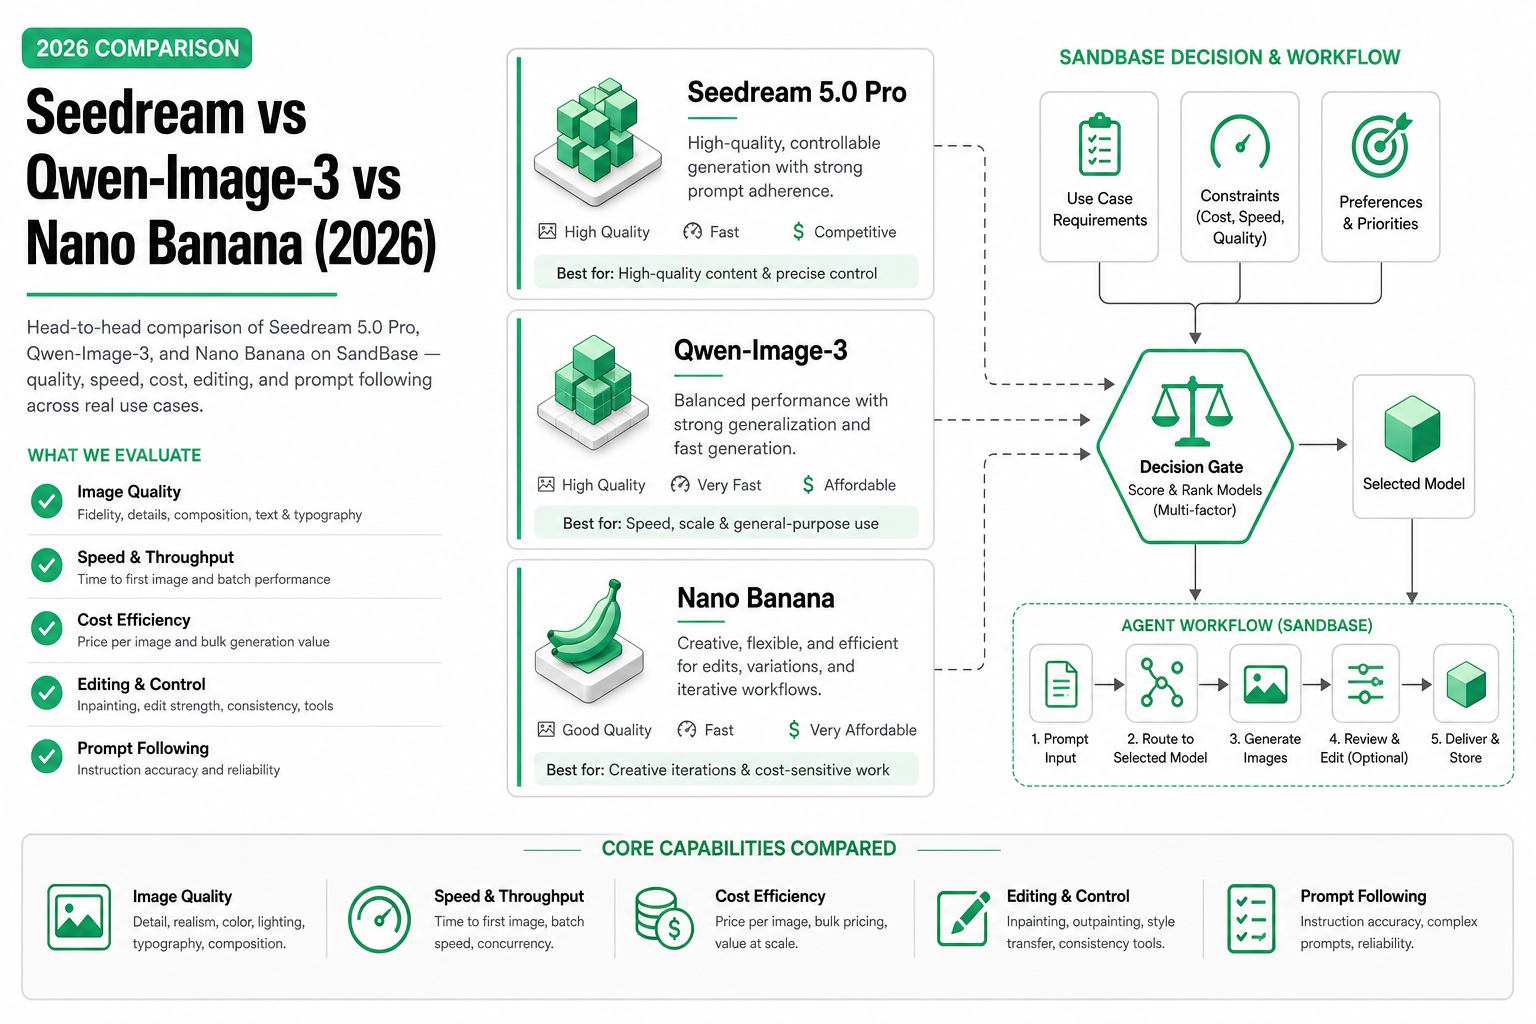
Head-to-head comparison of Seedream 5.0 Pro, Qwen-Image-3, and Nano Banana on SandBase — quality, speed, cost, editing, and prompt following across real use cases.
Read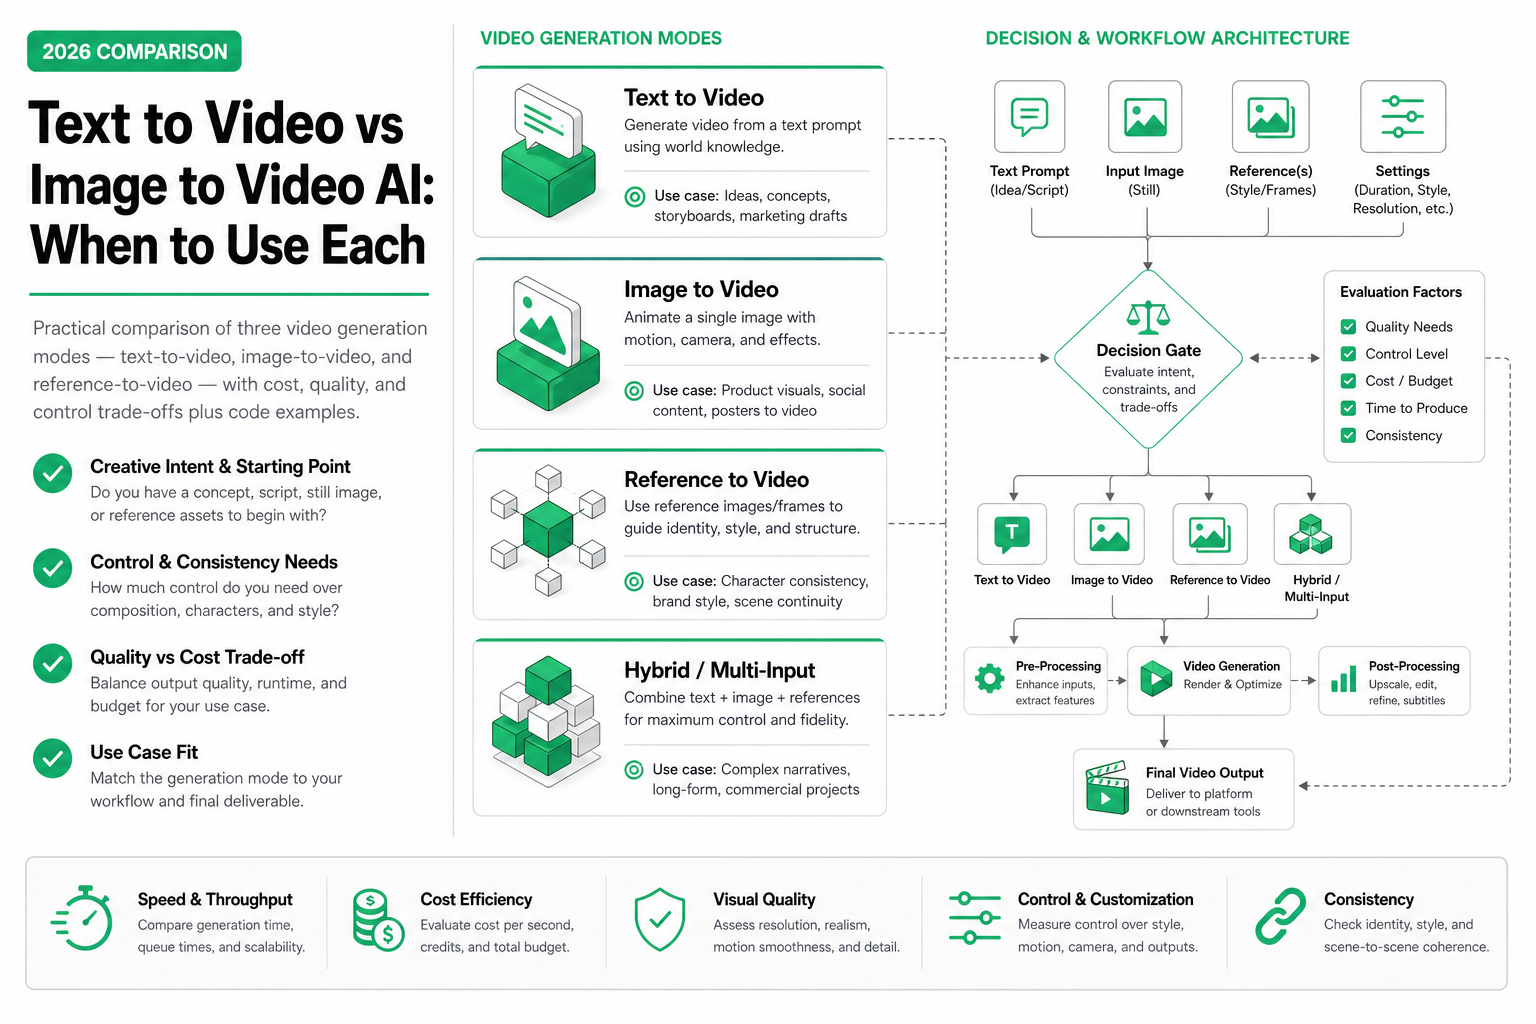
Practical comparison of three video generation modes — text-to-video, image-to-video, and reference-to-video — with cost, quality, and control trade-offs plus code examples.
Read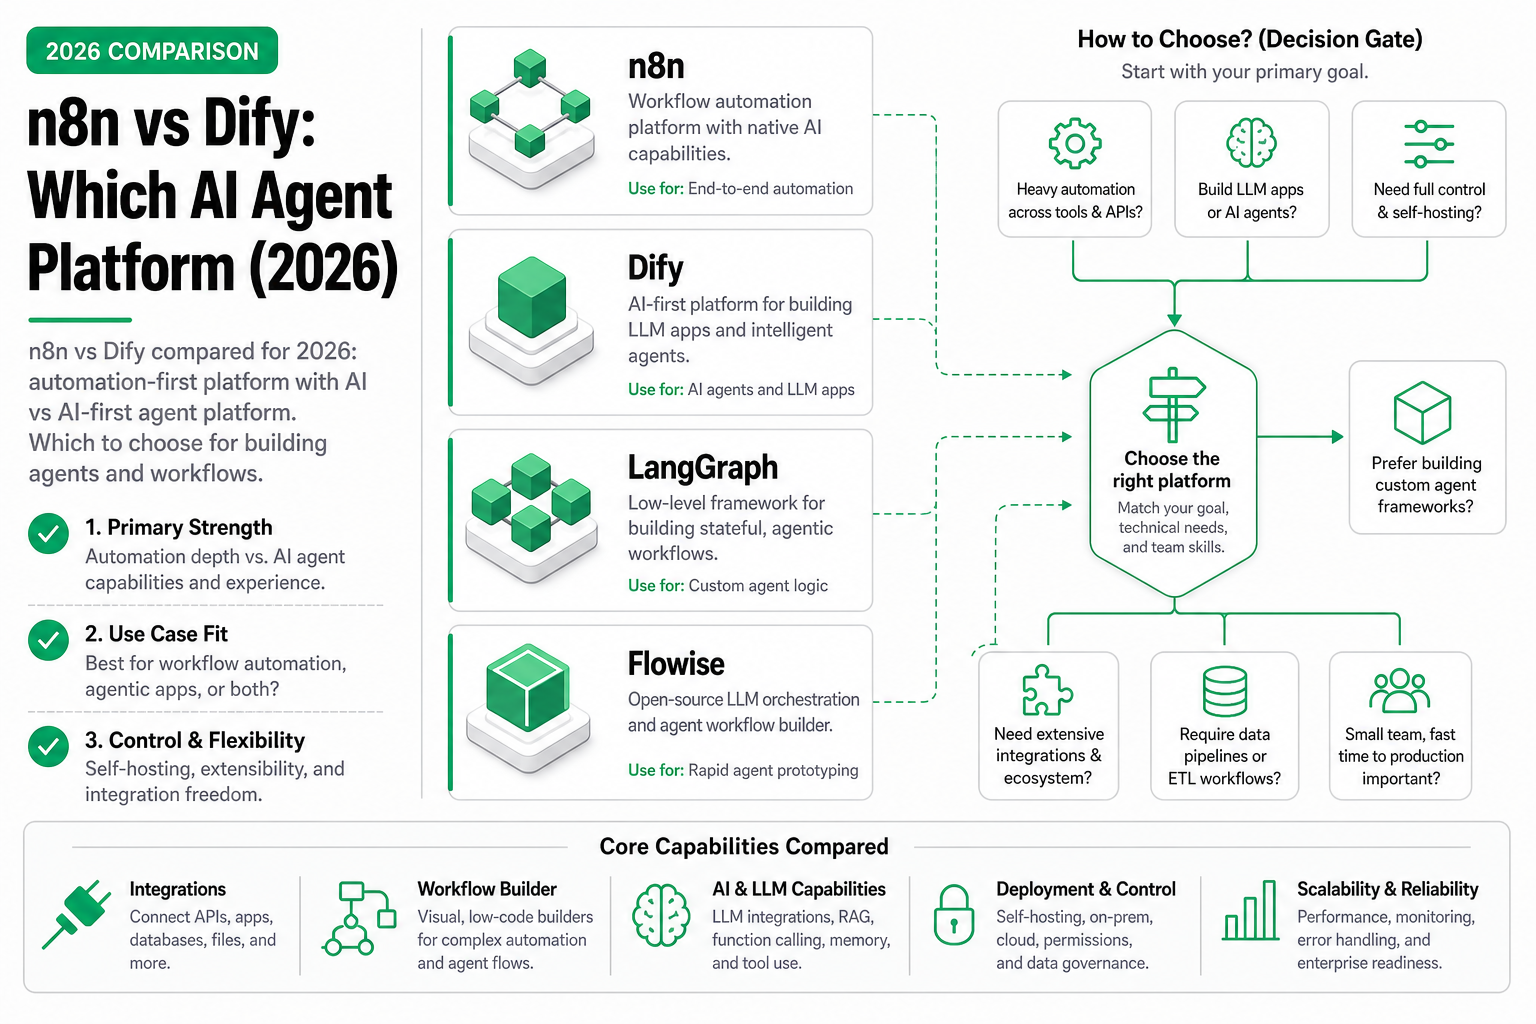
n8n vs Dify compared for 2026: automation-first platform with AI vs AI-first agent platform. Which to choose for building agents and workflows.
Read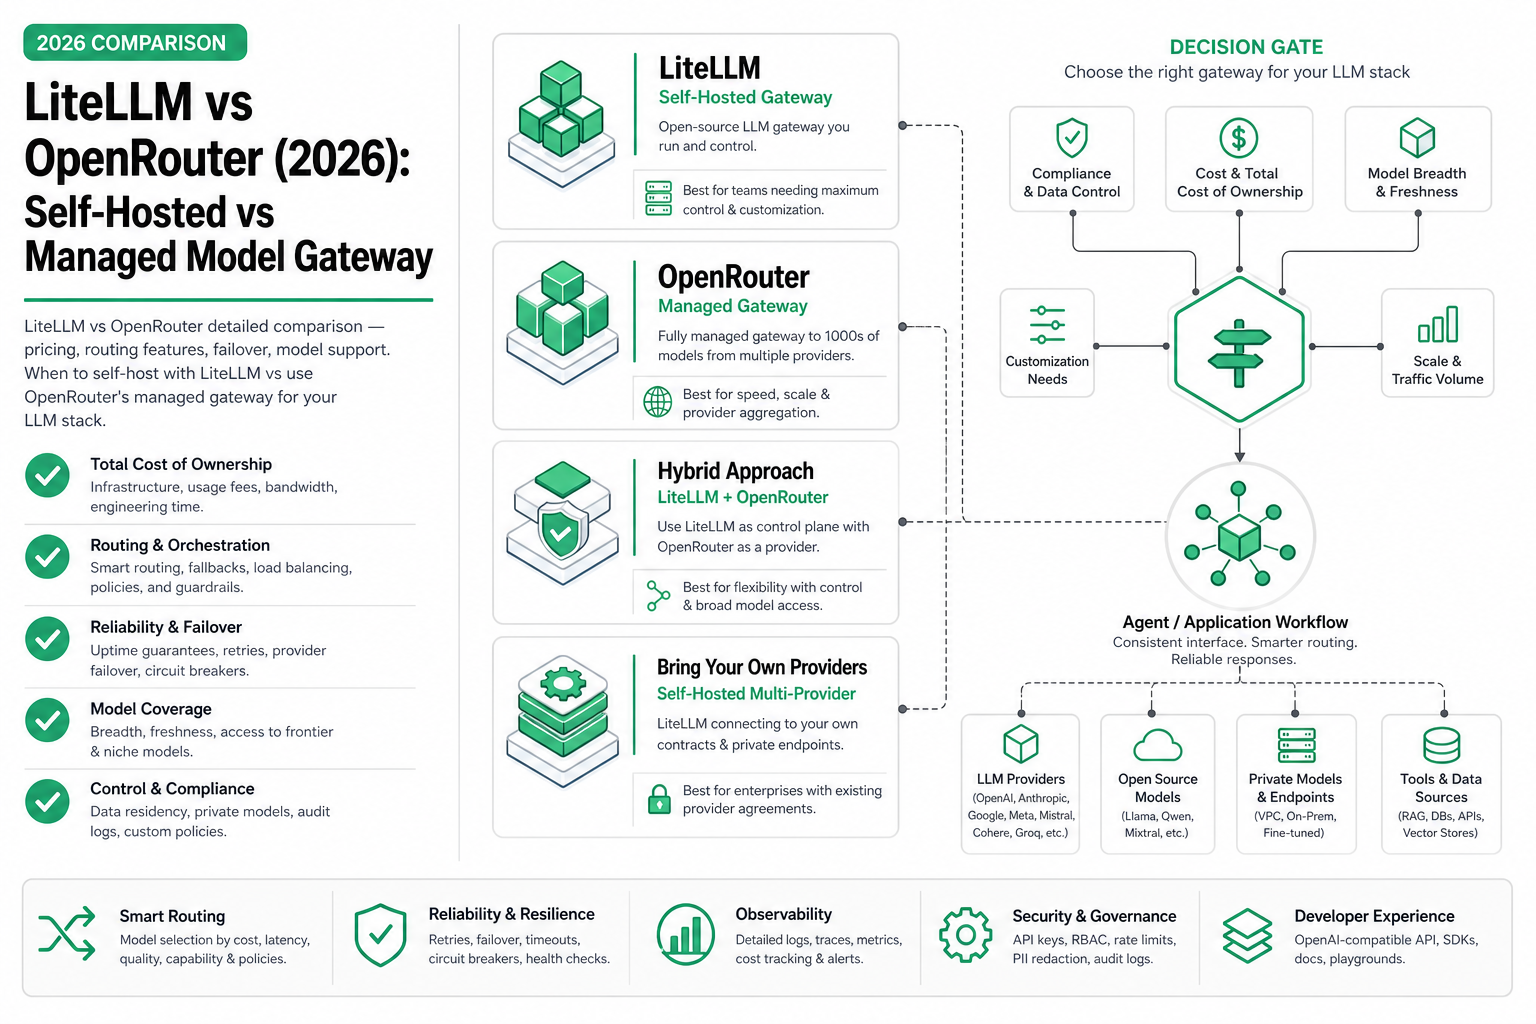
LiteLLM vs OpenRouter: self-hosted proxy vs managed gateway. We compare pricing, failover, model coverage, and latency to help you pick the right LLM router.
Read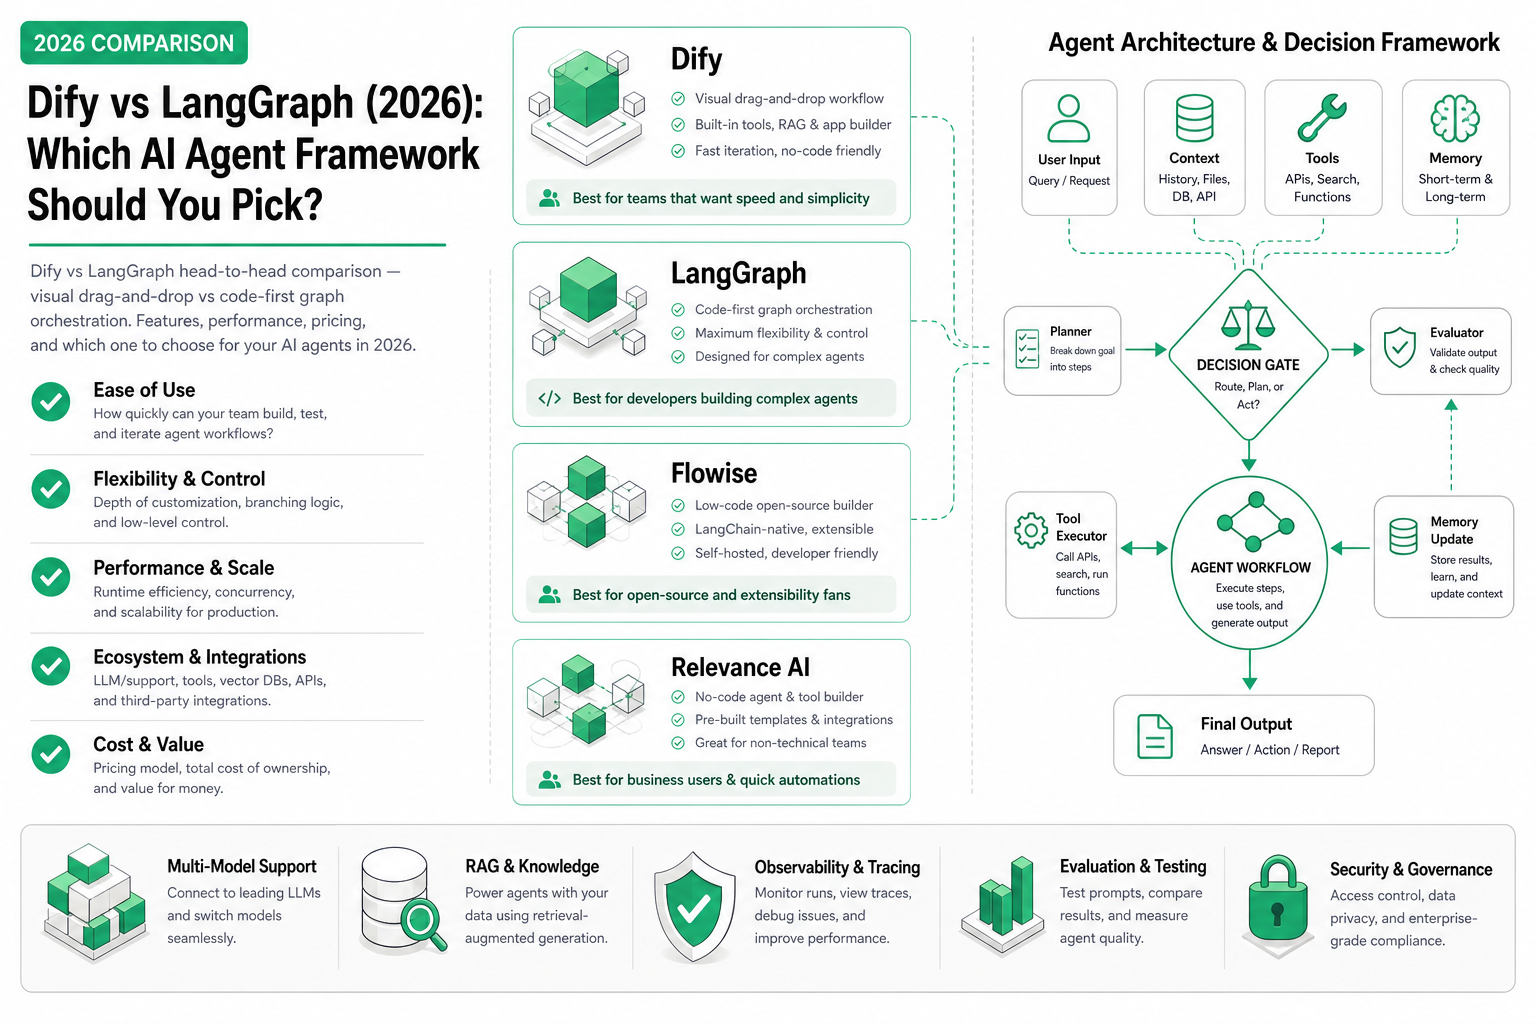
Dify vs LangGraph head-to-head comparison - visual drag-and-drop vs code-first graph orchestration. Features, performance, pricing, and which one to choose for your AI agents in 2026.
Read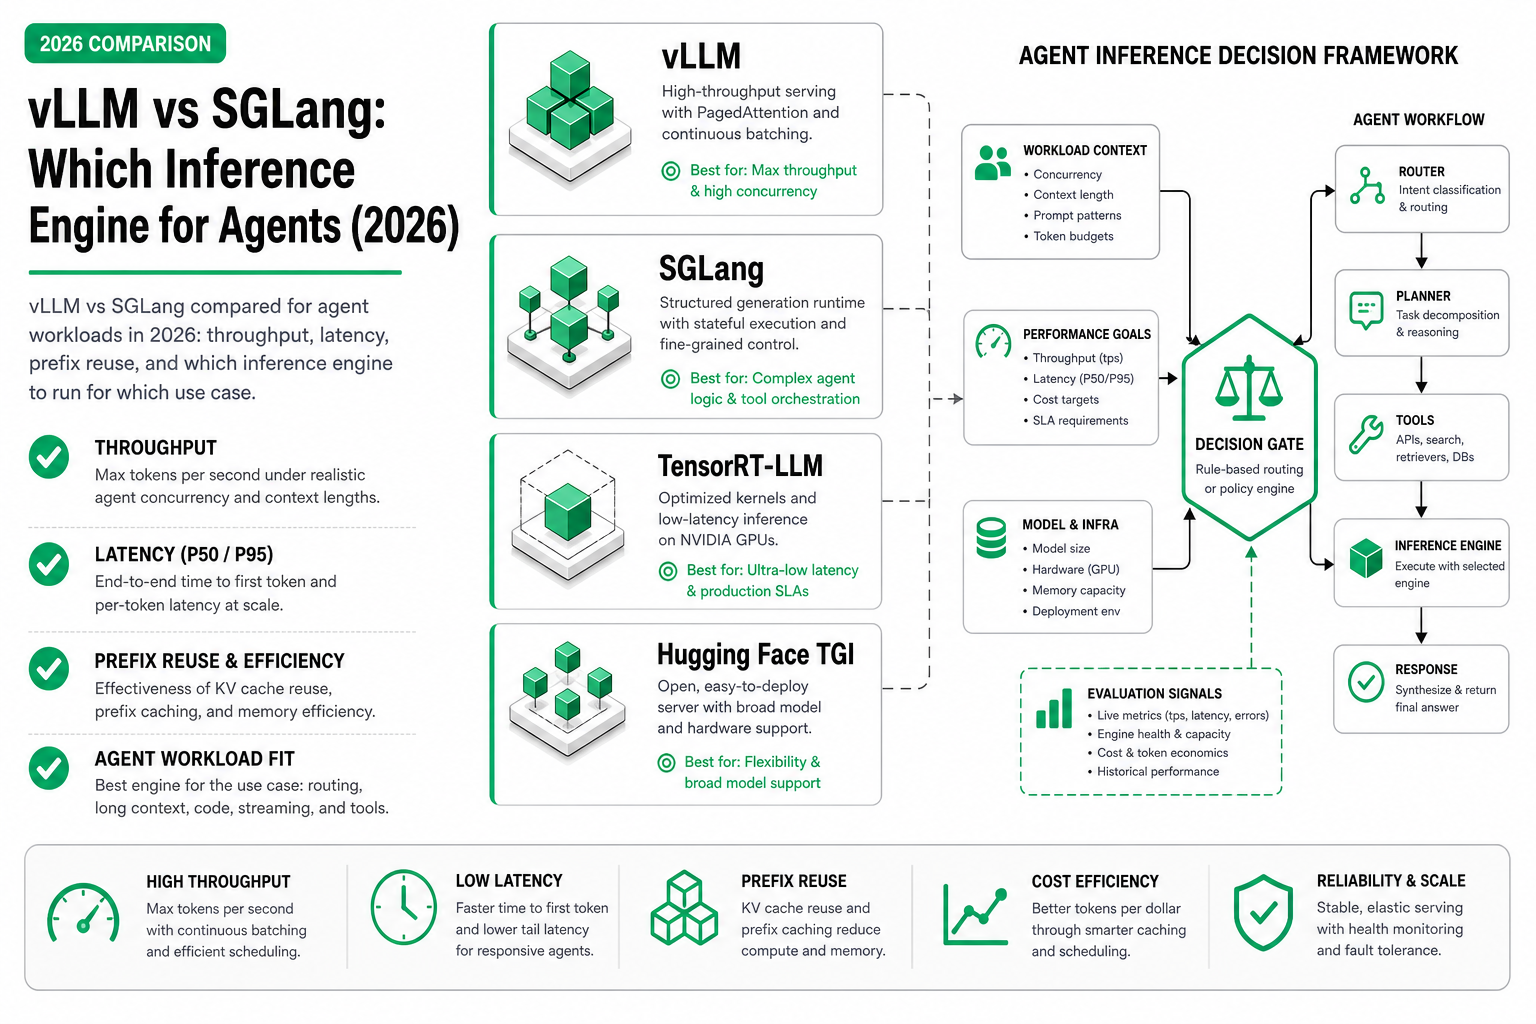
vLLM vs SGLang (2026) comparison for LLM serving and AI agents: which is better for throughput, latency, prefix caching, OpenAI API compatibility, and deployment fit?
Read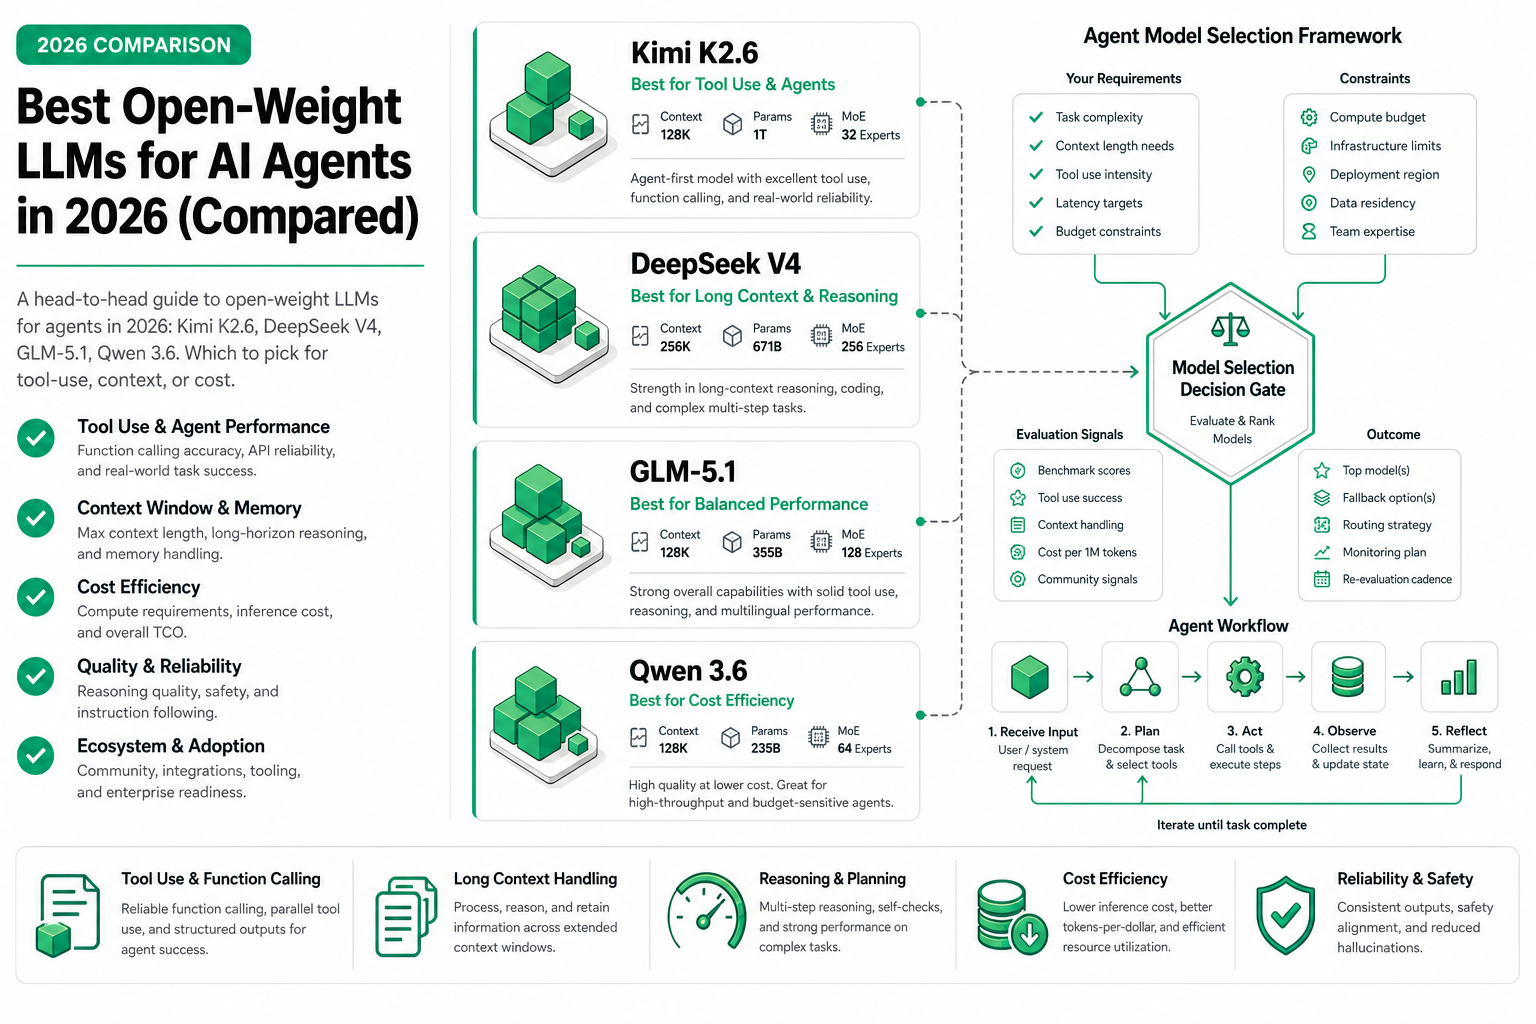
A head-to-head guide to open-weight LLMs for agents in 2026: Kimi K2.6, DeepSeek V4, GLM-5.1, Qwen 3.6. Which to pick for tool-use, context, or cost.
Read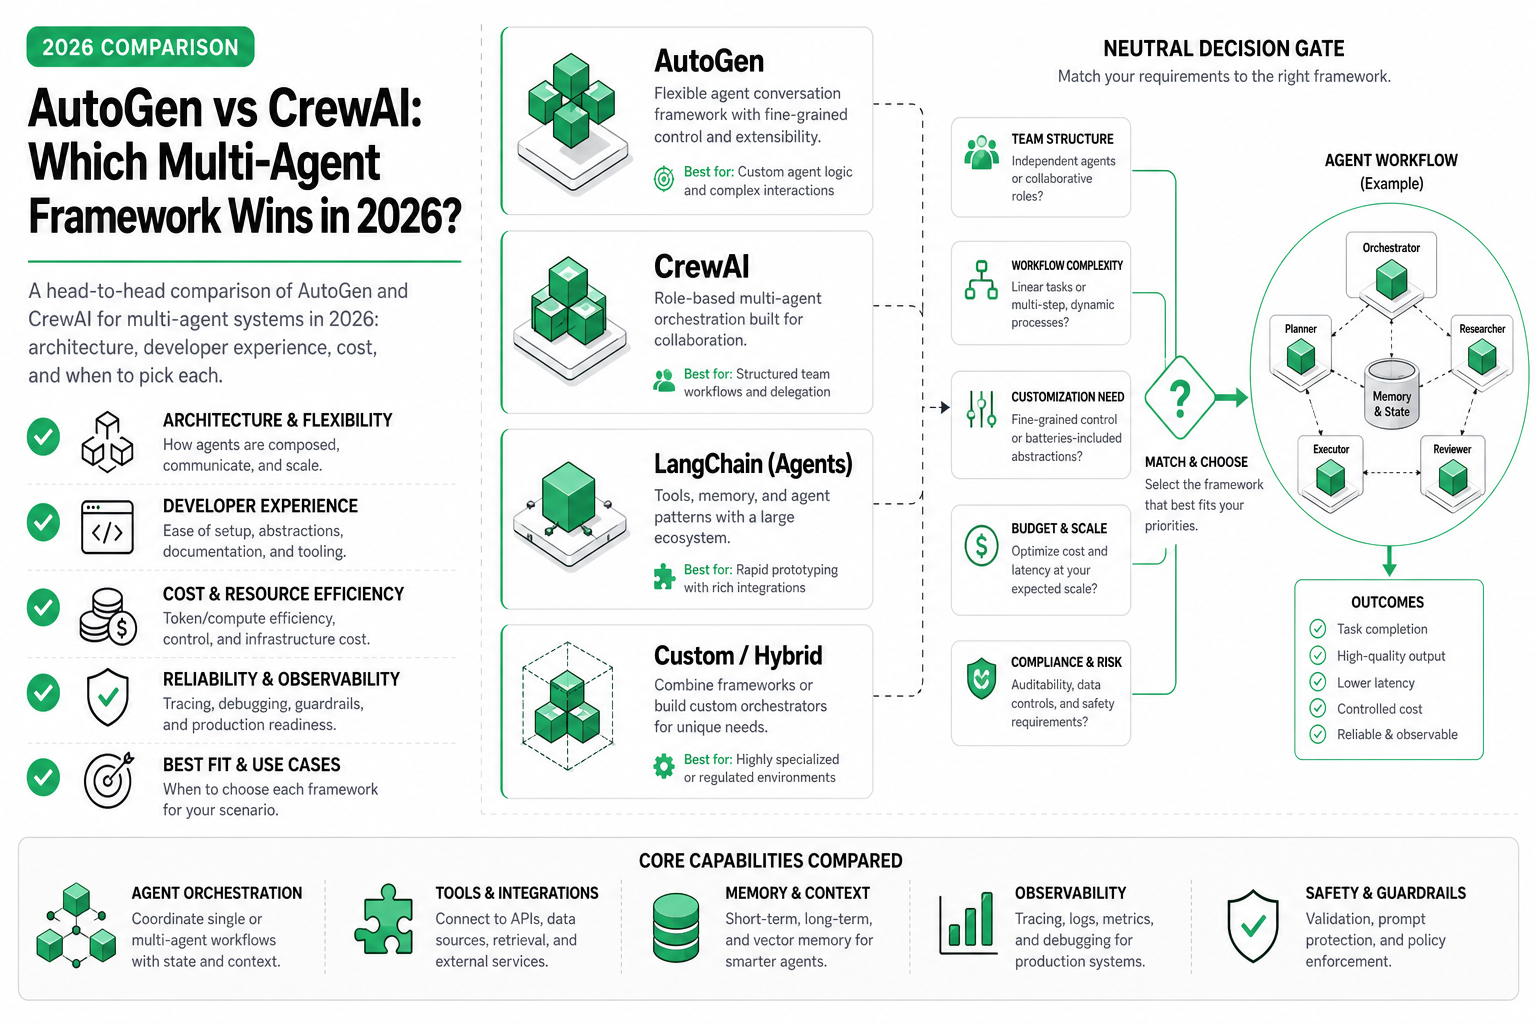
AutoGen vs CrewAI tested on real multi-agent tasks. AutoGen wins on flexibility; CrewAI wins on speed-to-ship. Full architecture and cost comparison inside.
Read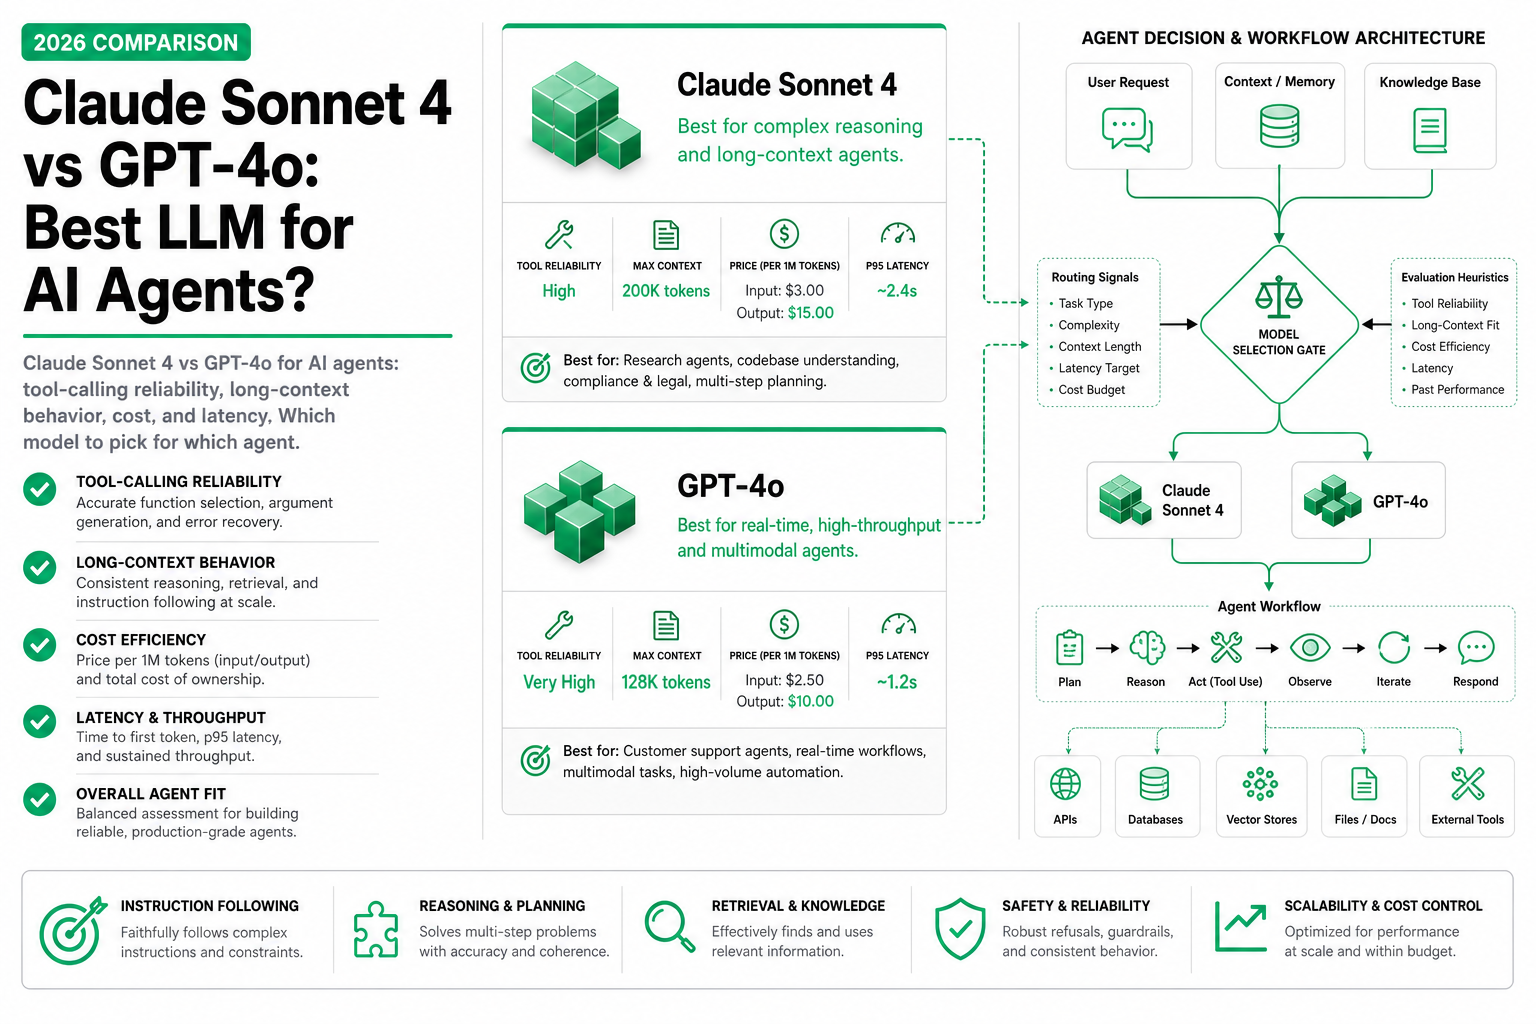
Claude Sonnet 4 vs GPT-4o for AI agents: tool-calling reliability, long-context behavior, cost, and latency. Which model to pick for which agent.
Read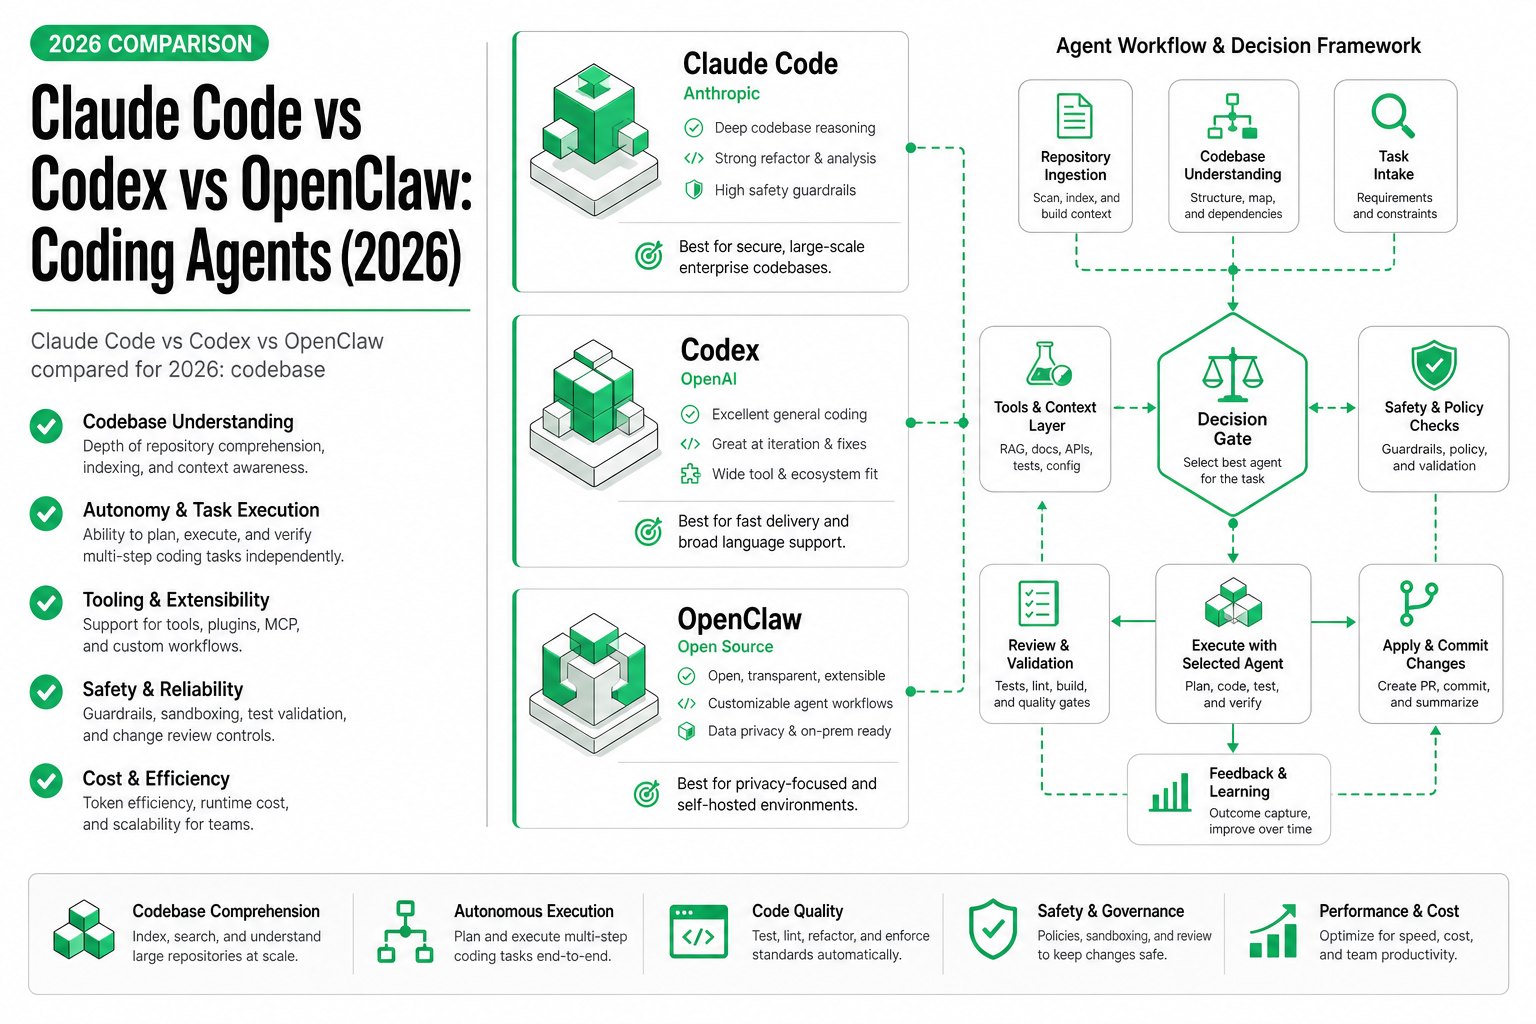
Claude Code vs Codex vs OpenClaw compared for coding agents in 2026. Benchmark results, pricing, context handling, and which to pick for your codebase size.
Read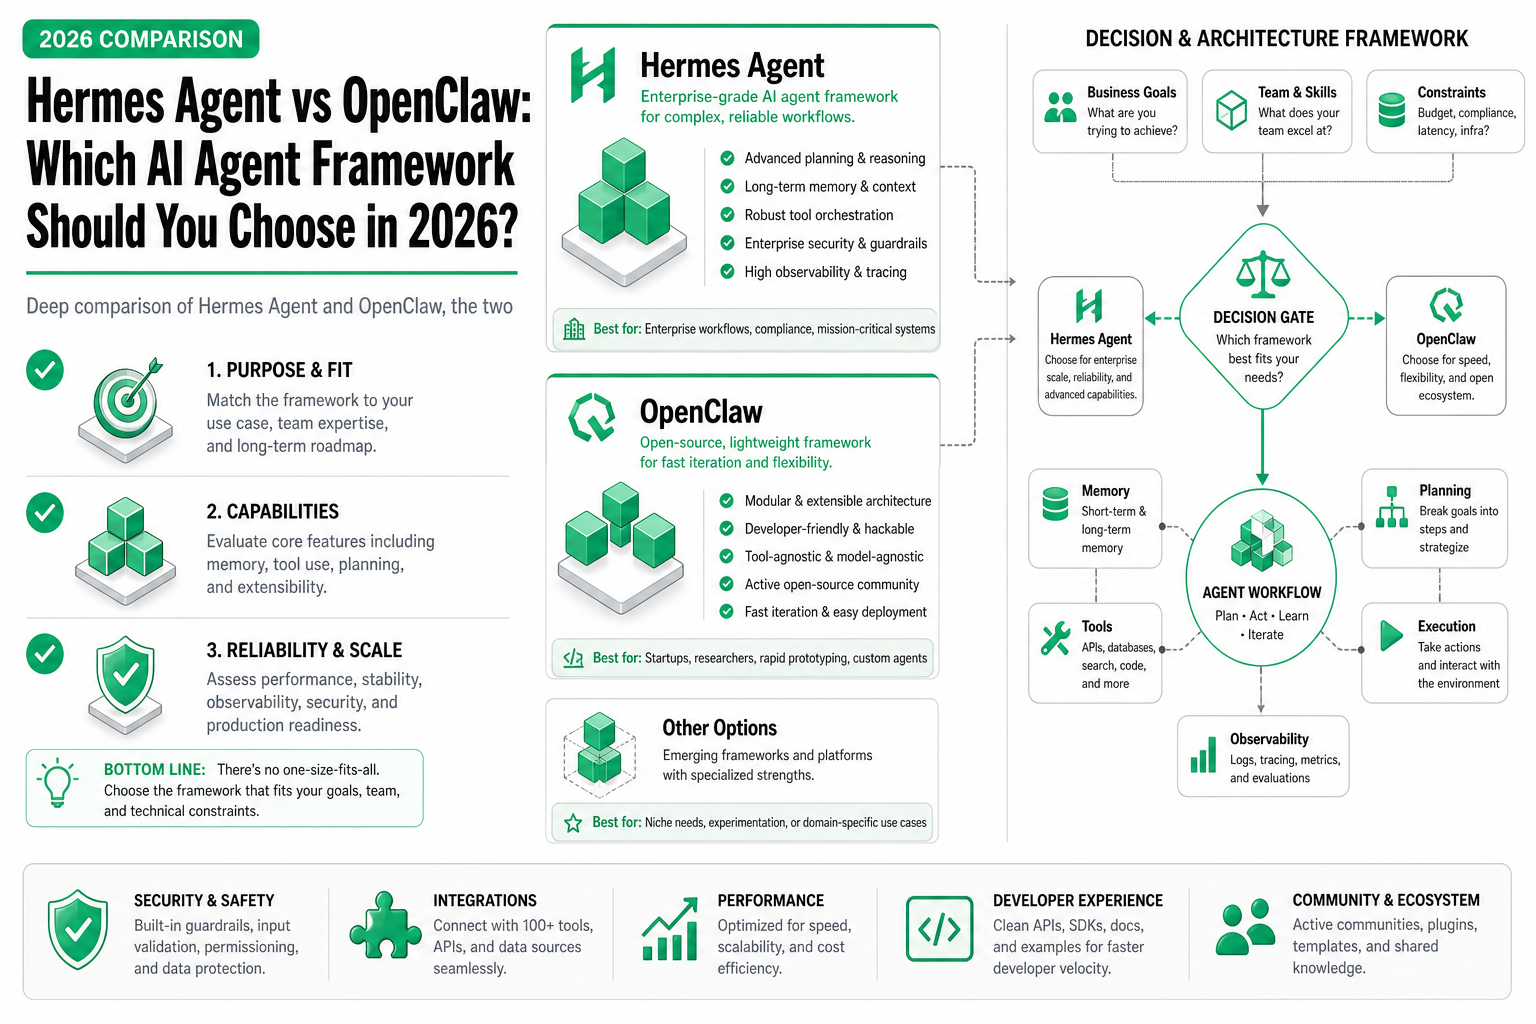
Deep comparison of Hermes Agent and OpenClaw for 2026. Architecture differences, self-improvement loops, deployment options, and when to choose each.
Read