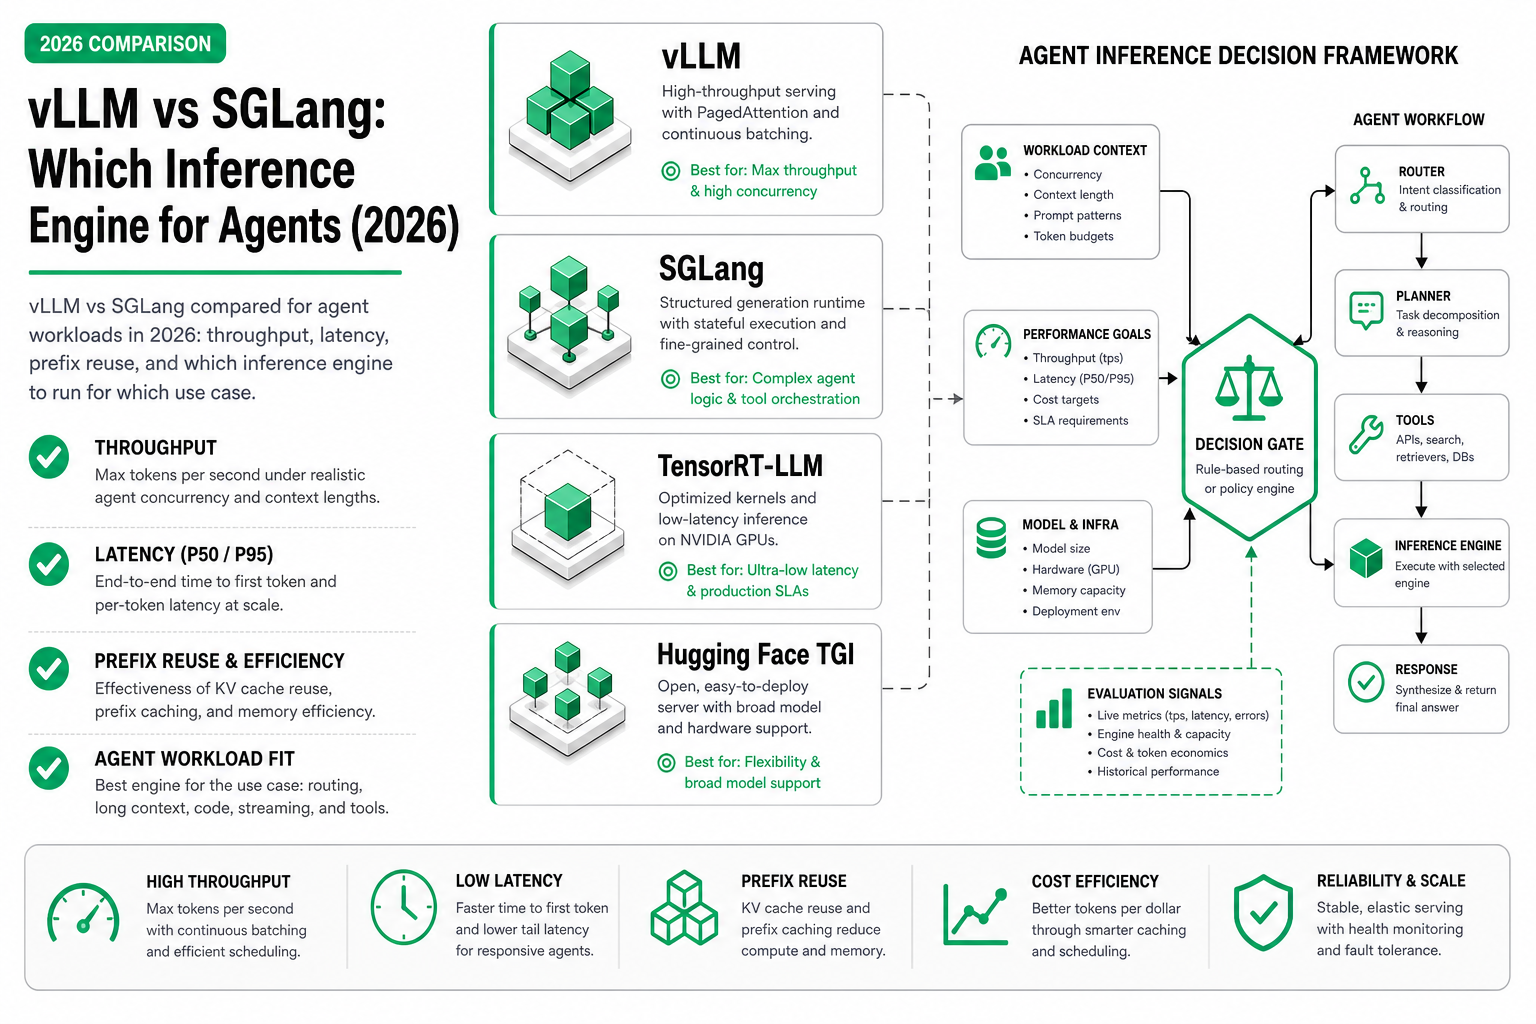
Model Comparison
vLLM vs SGLang (2026): Which Inference Engine Is Better?
vLLM vs SGLang (2026) comparison for LLM serving and AI agents: which is better for throughput, latency, prefix caching, OpenAI API compatibility, and deployment fit?
ReadvLLM vs SGLang (2026) comparison for LLM serving and AI agents: which is better for throughput, latency, prefix caching, OpenAI API compatibility, and deployment fit?
Read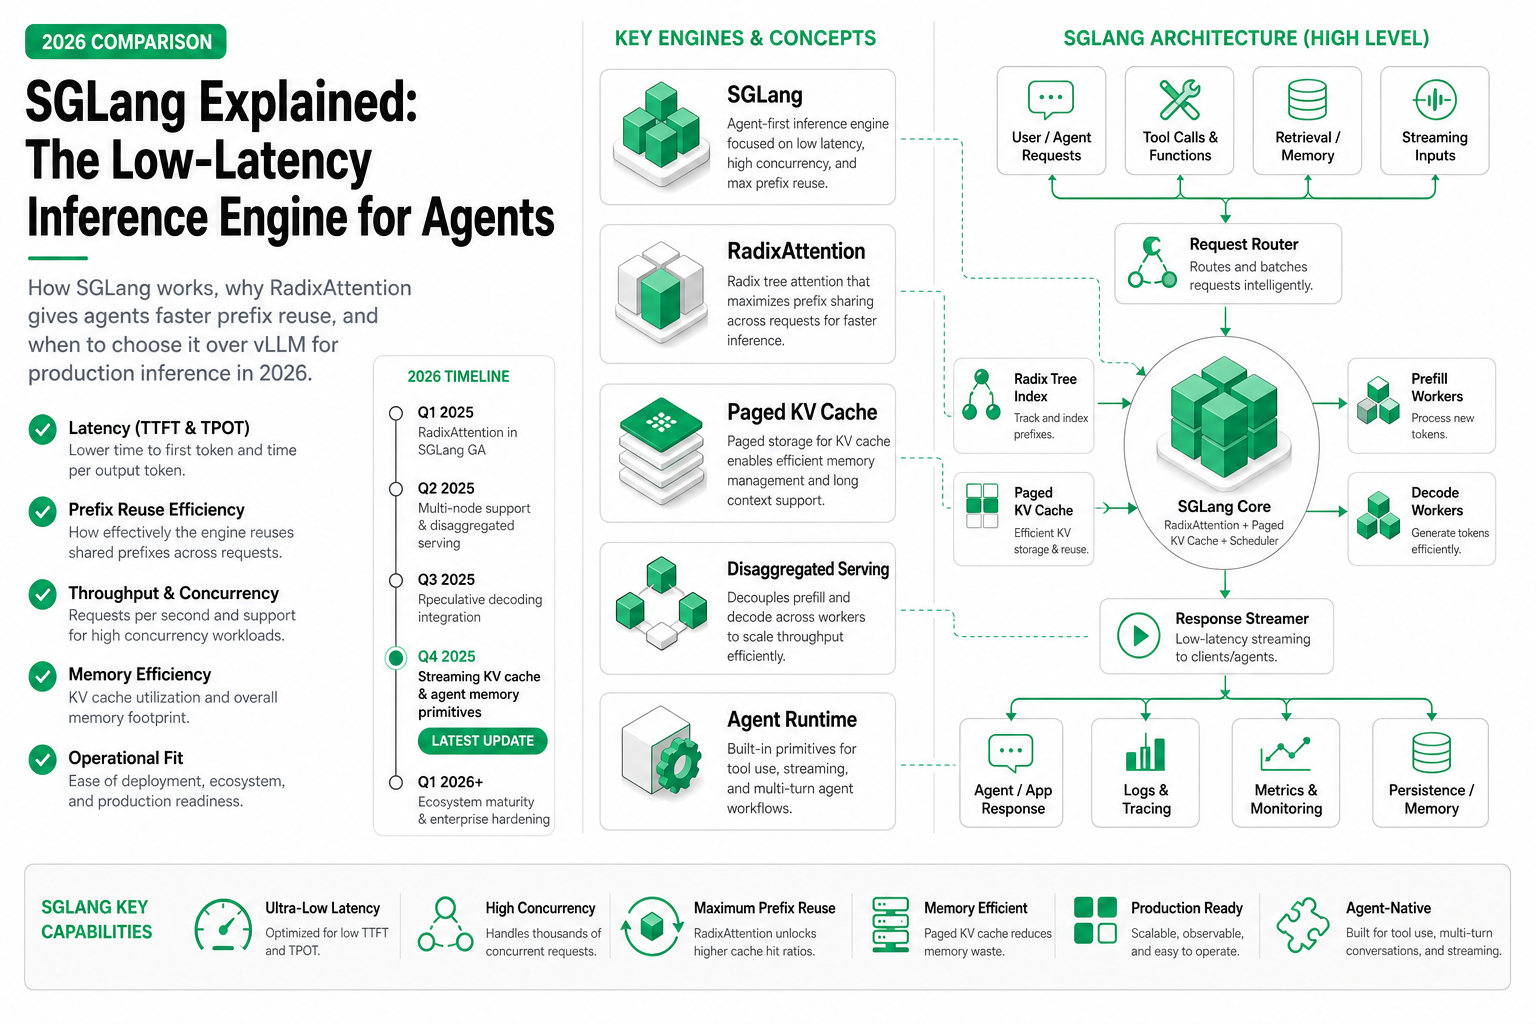
How SGLang works, why RadixAttention gives agents faster prefix reuse, and when to choose it over vLLM for production inference in 2026.
Read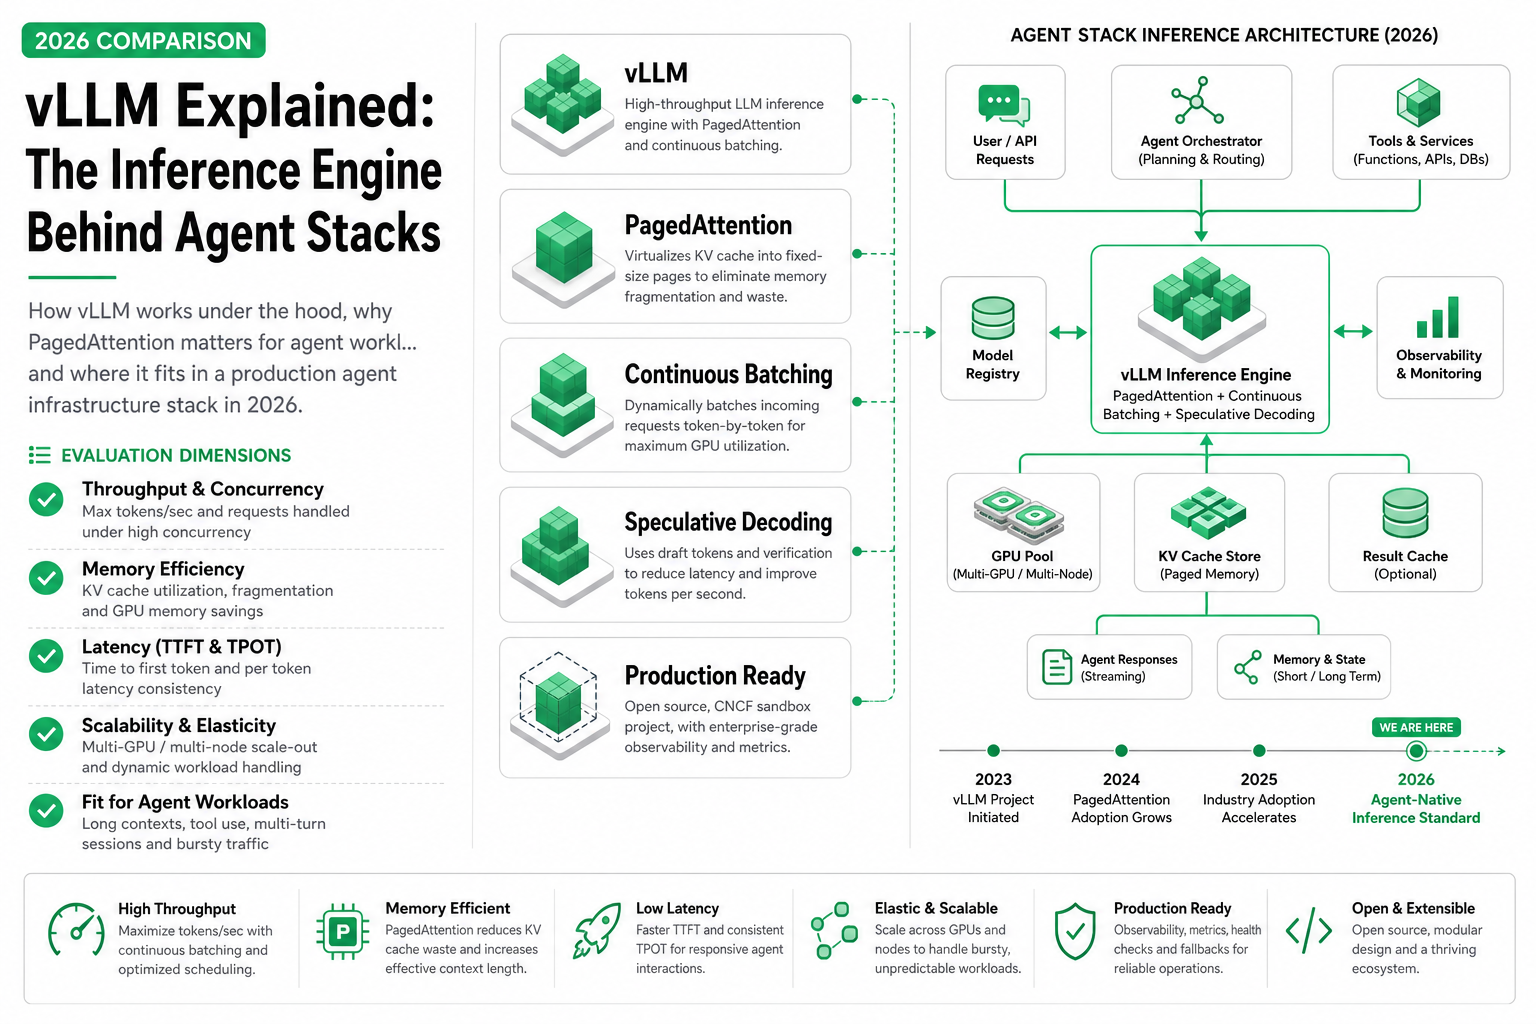
How vLLM works under the hood, why PagedAttention matters for agent workloads, and where it fits in a production agent infrastructure stack in 2026.
Read