GLM-5.3 Release Date & API Pricing (2026): Review, Benchmarks
GLM-5.3 release date and API pricing review: official coding and security benchmarks, API access, open-weight status, and changes from GLM-5.2.
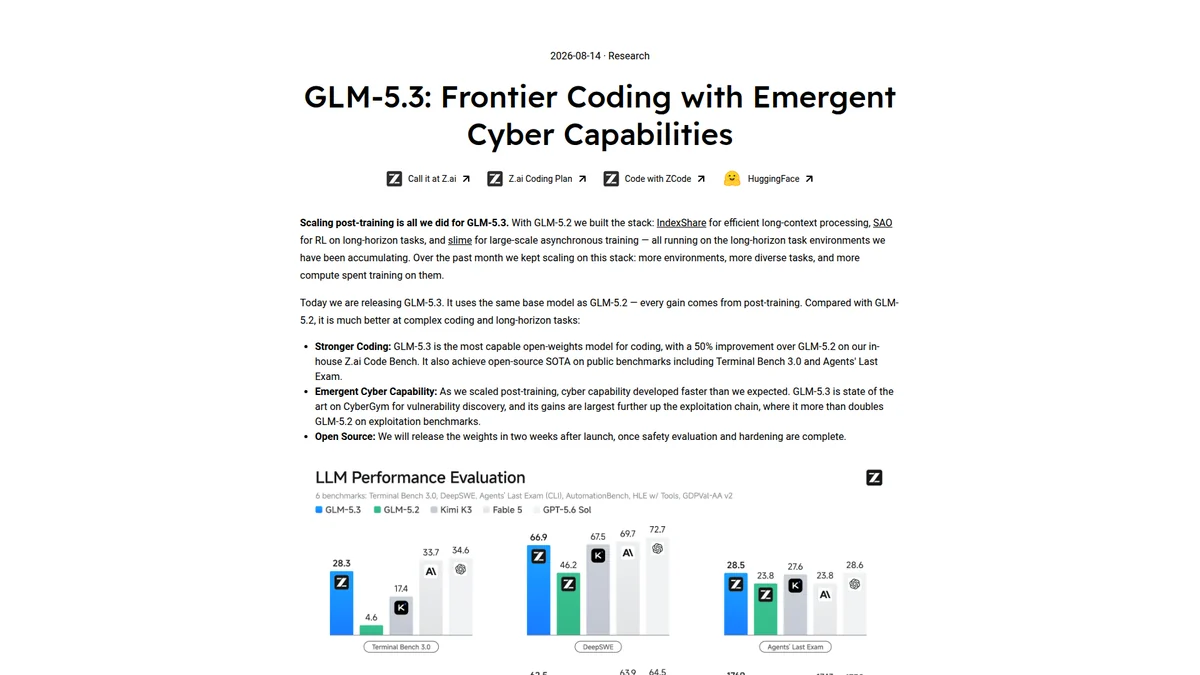
Status update: RELEASED. Z.ai announced GLM-5.3 on August 14, 2026. The official release describes post-training scaling across long-horizon coding and security environments. The benchmark numbers and vulnerability results below are Z.ai-reported results, not an independent reproduction; availability, API timing, and weight-release timing should be checked against the live announcement.
The primary source for this release watch is Z.ai’s GLM-5.3 announcement. This distinction matters: a vendor result can be useful for deciding what to test, but it is not the same as a cross-model benchmark run under a shared harness.
What Changed From 5.2 to 5.3
The base model is identical to GLM-5.2 (744B total, 40B active MoE, IndexShare architecture). All improvements come from post-training scaling:
- Tens of times more long-horizon task environments — some tasks equivalent to days of continuous engineering work
- Richer environment types — ML optimization clusters, security analysis frameworks, real-world development tooling
- Extended RL training — built on IndexShare, SAO, and Z.ai’s next-generation Slime framework
Z.ai’s claim: they may not have reached the intelligence ceiling of this base model yet.
Z.ai-reported coding benchmarks
The table below reproduces figures presented by Z.ai. Treat them as release evidence to validate, not as a universal ranking: benchmark versions, prompts, tools, sampling, and token budgets can change the result.
| Benchmark | GLM-5.2 | GLM-5.3 | Delta | Notes |
|---|---|---|---|---|
| Terminal-Bench 3.0 | 4.6 | 28.3 | +515% | Complex real-terminal tasks |
| DeepSWE v1.1 | 46.2 | 66.9 | +45% | Long-horizon software engineering |
| Agents’ Last Exam (CLI) | 23.8 | 28.5 | +20% | Cross-tool collaboration, long tasks |
| GDPval-AA v2 | — | 1769 | — | 44 professions, high-value knowledge work |
| Z.ai Code Bench (High) | — | 31.4% | — | Surpasses Claude Opus 4.8’s 29.5% |
The Z.ai Code Bench result is notable: GLM-5.3 achieves 31.4% accuracy in the High thinking mode with ~50K tokens per task, while Claude Opus 4.8 reaches 29.5% but needs ~120K tokens. GLM-5.3 finds shorter execution paths.
Z.ai-reported cybersecurity capabilities
Z.ai presents these results as emergent security capabilities. They require independent safety review and reproducible evaluation before production or offensive-security use.
 Z.ai’s OpenVuln space on HuggingFace — continuous security audits for open-source projects, powered by GLM-5.3.
This is the unexpected headline. Z.ai didn’t specifically train for cybersecurity — it emerged from pushing coding capabilities into more constrained environments. Their framing: “Security work is fundamentally constrained programming.”
| Benchmark | GLM-5.2 | GLM-5.3 | Mythos 5 | GPT-5.6 Sol | Task |
|---|---|---|---|---|---|
| CyberGym | 77.2% | 84.5% | 83.8% | 83.6% | White-box source code → trigger faults → identify vulnerabilities |
| ExploitBench | 24.4% | 54.4% | 78.0% | 76.5% | Understand real vulnerabilities → create exploits |
| ExploitGym (2h) | 29 tasks | 105 tasks | 181 tasks | — | Time-bounded exploit completion throughput |
| ExploitGym (6h) | 39 tasks | 130 tasks | 247 tasks | — | Extended time budget |
The pattern: the closer to the “discovery” end of the vulnerability chain, the more competitive GLM-5.3 is. It matches or beats Mythos 5 on code review and vulnerability identification (CyberGym: 84.5% vs 83.8%). It still trails significantly on full exploit creation (ExploitBench: 54.4% vs 78.0%).
Real-World Vulnerability Discovery
Since GLM-5.2, Z.ai collaborated with Tsinghua University, Nankai University, and multiple security teams (Yunqi Wuxian, NSFOCUS, CyberKunlun, DARKNAVY, and others). Results:
- 2,436 vulnerabilities discovered (after deduplication)
- 1,097 classified as medium or high severity
- Some vulnerabilities dormant for up to 45 years
- Spanning 269 projects: system kernels, browsers, OS components, internet protocols
- Estimated market value: 30 million RMB (referenced against Zerodium, Crowdfense, Apple Security Bounty, Pwn2Own pricing)
Notable cases:
- DNS protocol vulnerability (dormant ~40 years): amplification factor up to 80,000×, potentially affecting 90%+ of global DNS systems
- Cursor IDE vulnerability: Rust/Electron architecture risk enabling arbitrary file write
- National-scale messaging app vulnerability: zero-click remote exploitation via protocol-level flaw
- Microsoft Exchange-level vulnerabilities: 3 critical bugs in email/Office systems (acknowledged as “Kunlun Lab & GLM”)
- Humanoid robot fleet vulnerability: remote hijacking of 1000+ robots simultaneously
”Open Shield” Initiative
Z.ai is positioning GLM-5.3’s cybersecurity capabilities as an open-source public good, explicitly contrasting with Anthropic’s approach of providing Mythos only to ~150 large enterprises:
- Continuous security audits for major open-source projects (free): OpenVuln on HuggingFace
- Free model credits for open-source maintainers (for security audit and defense tasks)
- Code audit feature in ZCode — bringing security review into daily dev workflows
Availability and Timeline
| Channel | Status | When |
|---|---|---|
| ZCode (coding tool) | ✅ Live now | Aug 14, 2026 |
| AutoClaw (productivity tool) | ✅ Live now | Aug 14, 2026 |
| GLM Coding Plan | ✅ All users, subscriptions open | Aug 14, 2026 |
| Third-party tools | ✅ Early access | TraeWork, TraeCode, Coze, WorkBuddy, CodeBuddy, Qoder, QwenWork, CatPaw, JoyCode, OpenCode |
| API | 🔜 Coming soon | Days/weeks |
| Open weights | 🔜 Two weeks | After security hardening |
| License | Expected Apache-2.0 | TBD with weight release |
Architecture: Post-Training, Not Pre-Training
 GitHub zai-org/GLM-5 — the repository where GLM-5.3 weights will be published within two weeks.
The key technical story: GLM-5.3 uses the exact same base model as GLM-5.2 (744B/40B MoE with IndexShare). All gains come from post-training:
- IndexShare — long-context efficiency (2.9× FLOP reduction at 1M tokens)
- SAO (Self-play Alignment Optimization) — RL alignment technique
- Slime framework (next-gen) — Z.ai’s proprietary RL infrastructure
Training environments include real ML optimization clusters where the model uses the same compute, storage, documentation, and experiment systems as human algorithm engineers — performing end-to-end measurable acceleration.
Safety Architecture
GLM-5.3 includes Z.ai’s most robust risk review system, built on defense-in-depth:
| Layer | Role | How |
|---|---|---|
| Outer classifier | Flag and block mass abuse | Lightweight model, high throughput |
| Reasoning monitor | Real-time intent review during inference | Detects harmful intent during generation |
| Deep safety alignment | Self-refuse attack requests | Only defense that survives open-weight release |
The system distinguishes intent, not keywords — critical because attack and defense code look identical at the surface level. Risk is graded by task type (security Q&A, blue team defense, CTF, vulnerability discovery, exploitation, penetration testing, real intrusion) with per-category threshold tuning.
Most sensitive capabilities are restricted to verified users via Z.ai’s “Cybersecurity Trusted Access” program.
Comparison: GLM-5.2 → GLM-5.3
| Spec | GLM-5.2 | GLM-5.3 |
|---|---|---|
| Base parameters | 744B (40B active) | 744B (40B active) — same |
| Architecture | IndexShare MoE | IndexShare MoE — same |
| Context window | 1M tokens | 1M tokens — same |
| Terminal-Bench 3.0 | 4.6 | 28.3 |
| DeepSWE v1.1 | 46.2 | 66.9 |
| CyberGym | 77.2% | 84.5% |
| ExploitBench | 24.4% | 54.4% |
| License | Apache-2.0 | Expected Apache-2.0 (pending) |
| Weights | Open | Open in 2 weeks |
| Key innovation | IndexShare architecture | Post-training scaling to intelligence ceiling |
What This Means for Developers
If you’re using GLM-5.2 today: API compatibility is expected. Wait for the API launch (days) then test in staging.
If you need open weights: Two-week wait for security hardening. The weights will include safety alignment that limits offensive use while preserving defensive capabilities.
If you’re building security tooling: GLM-5.3 is immediately interesting for code review, vulnerability scanning, and defensive analysis. For full exploit development, Mythos 5 still leads.
If you’re on SandBase: We’ll add GLM-5.3 to our model catalog as soon as the API is publicly accessible. For GLM-5.2 today, see our model catalog.
For the earlier GLM-5.1 story, see our GLM-5.1 open-weight deep dive. For how open-weight models compare in the current landscape, see Best Open-Weight LLMs for Agents (August 2026).
FAQ
Is GLM-5.3 a new architecture?
No. Same base model as GLM-5.2 (744B/40B MoE with IndexShare). All improvements from post-training RL scaling.
When can I use it via API?
Z.ai says “soon” — likely days to weeks. ZCode and AutoClaw are live now.
When are weights released?
Two weeks from August 14, approximately August 28. Security hardening must complete first.
Does it beat Claude Fable 5?
On Z.ai’s internal Code Bench: GLM-5.3 (31.4%) beats Claude Opus 4.8 (29.5%) with 60% fewer tokens. On public benchmarks, it’s the top open-source model but hasn’t been directly benchmarked against Fable 5 on the same evaluations yet.
Should I use it for offensive security work?
The safety system restricts offensive capabilities. Defensive use (code review, vulnerability scanning, patch development) is fully supported. Offensive capabilities require Z.ai’s “Cybersecurity Trusted Access” verification.
See all GLM models on SandBase: Z.ai Vendor Page | GLM 5.2